

Welcome to issue #48 of the Marketing with AI Weekly Roundup. Published every Sunday, it shares the top stories, playbooks, data and quick hits from the world of Marketing with AI over the last 7 days.
Subscribe to receive the week's most important AI marketing stories direct to your inbox.
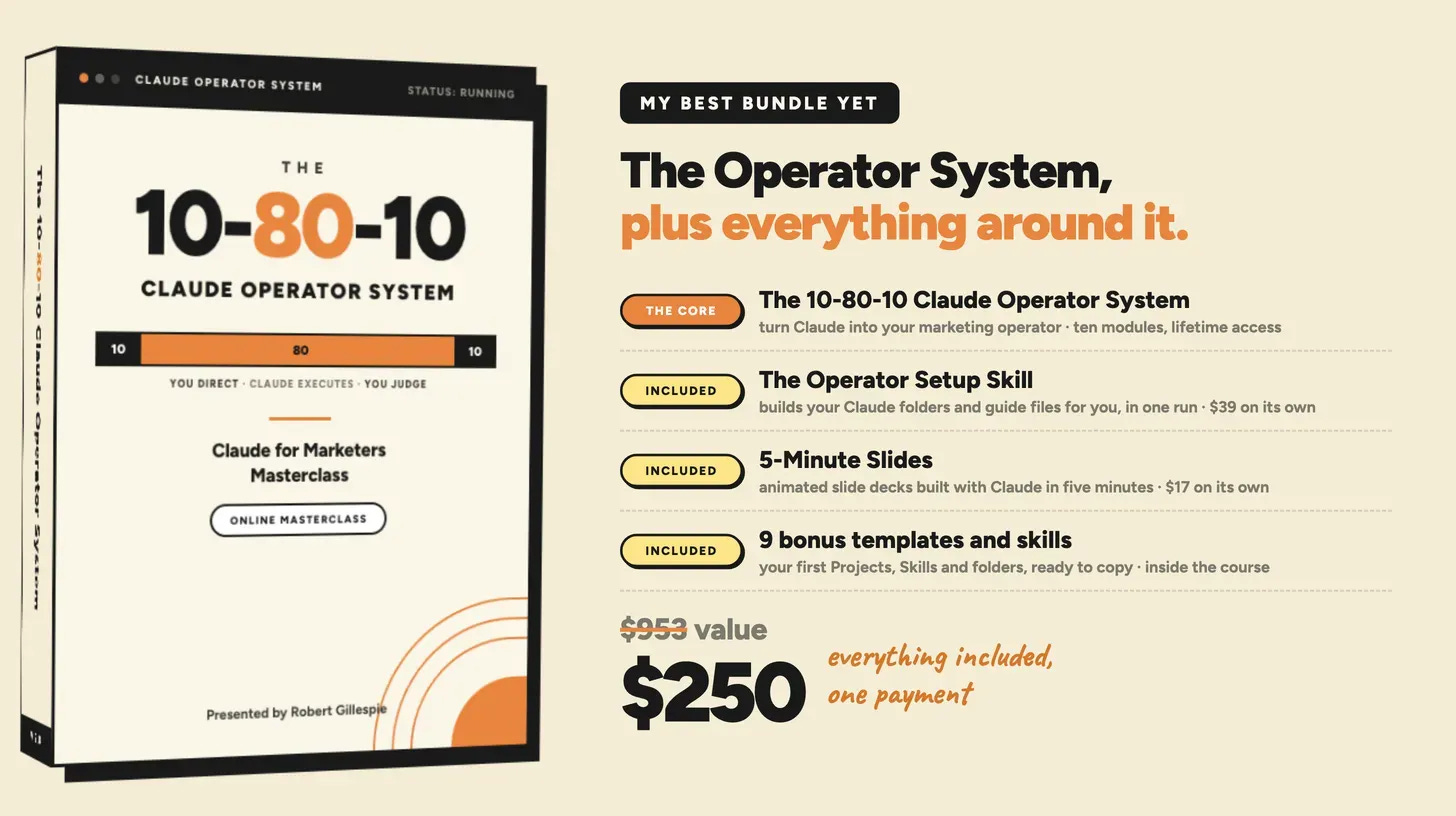
MY BEST BUNDLE YET FOR MARKETERS (LIMITED TIME OFFER):
For marketers who want their hours back. The full Operator System, the Setup Skill that builds your working environment, and 5-Minute Slides, together for the first time. $250, everything included. (Individual price $953).

Last week we led with Anthropic marking everything Claude writes with an invisible watermark. It turns out that was only half the story.
In the same week, and we missed it, Google made its own visible watermark optional on every image, video and song the Gemini app produces, while quietly leaving the invisible one switched on. Two companies, opposite directions, same destination.
On Monday, Google’s Smart Bidding change went live on budget-limited campaigns, the one we made our lead story a fortnight ago. On Tuesday, the IAB published the second version of its AI disclosure framework and drew a line most marketers will be surprised by, because AI-written copy sits on the no-disclosure side of it.
And running underneath the whole week, Search Console’s Generative AI report has been wrongy understating your impressions since 13 August, which means a lot of teams are about to present a decline that never happened.
Elsewhere, Microsoft turned on AI Max globally and started removing the bid ceiling, Reddit lost 86% of its ChatGPT citations in four days, and Gmail finally switched off the domain reputation score you were told to stop relying on two years ago.
Below: four stories to act on, three workflows worth stealing with the real costs attached, and one deadline that closes nine days from now.
Let’s get into it…
1. Google’s bidding change went live on Monday, and anyone showing you what it did is reading noise
On 17 August 2026, Google began rolling out the change we led with on 8 August. Campaigns carrying a “Limited by budget” status while running Target CPA or Target ROAS now optimise toward the target you set, rather than settling wherever the constrained budget happened to leave them.
The mechanics, stated plainly. A Search campaign carrying a £10 target cost per acquisition that has been delivering at £5 will now drift upward toward £10. Total spend does not rise, because the budget still caps it. Volume falls instead, and your reported cost per conversion climbs to meet the number you typed into a settings field, possibly years ago.
What Google’s framing leaves out. Google describes this as making performance more predictable. The practitioner reading, and it is supported by Google’s own documentation, is that the old behaviour was never generosity. Bids were being quietly lowered so that a capped daily budget lasted the full day. That is why a £10 target so reliably produced a £6 result. Yesterday’s overperformance was throttling, and this change removes it.
Three conditions must all hold. Ginny Marvin, Google’s ads product liaison, narrowed the scope more than most coverage has admitted. The campaign must carry a target, must be limited by budget, and must currently be beating that target. Miss any one and nothing happens to you. She also confirmed for the first time that targets set at ad group level are in scope, which matters because lead generation accounts are full of them.
It runs in one direction only. Asked directly whether campaigns missing their targets get a corrective push in the other direction, the answer was no. Google will pull an overachieving campaign up to its target and will not push an underachieving one down. And below roughly seven conversions, Google calculates no recommended target at all, so thin-volume B2B campaigns get no guidance from the tool that is about to change their delivery.
A second change landed the following day, and almost nobody covered it. From 18 August, Google automatically assigns a customer type to every eligible conversion-based Customer Match list that has not been classified manually. The unclassified state no longer exists. Those labels feed straight into Smart Bidding, so if you run a new-customer acquisition goal, the label decides who counts as new. For a B2B account where a conversion is a demo request rather than a purchase, Google’s inference that someone is an existing customer is very likely wrong, and a mislabelled list means paying acquisition bids for people already in your pipeline. Google exposes nine customer-type labels if you set them yourself. Its automatic assignment uses three. The opt-out window has closed, though you can still relabel. This affects only lists Google builds from Enhanced Conversions data, so manually uploaded Customer Match lists are untouched.
The third piece is a deadline. Google has disclaimed its own forecasts. Its guidance says Performance Planner and other budget and bid forecasts may contain inaccuracies during the transition, and advises caution from 17 to 31 August. That window is open right now and closes on Monday week.
Why it matters / what to do: The most useful thing you can do this week is nothing dramatic. There is no credible before-and-after data anywhere, from anyone, and there is a structural reason for that. The rollout is staged over several weeks rather than flipped in a day, and Google’s own guidance is to let one or two conversion cycles run before reading results. For a B2B account with a two to three week sales cycle and weekly offline conversion imports, that means four to six weeks, not five days. First reliable readings land somewhere between mid-September and mid-October, which is to say in the middle of your Q4 planning.
So record a baseline instead of reacting to one. Export your current target-versus-actual performance now, while you still have a clean pre-change read. Then filter for exposure: flag campaigns where actual cost per acquisition is 20% or more below target, or actual return on ad spend is 20% or more above. Use a twelve-month lookback on the budget-limited flag rather than today’s status, because Google’s own notification trigger covers any campaign that hit its cap at any point in the last year, and filtering on today under-reports your exposure badly.
Rank what you find by money at risk rather than by the size of the gap. A 20% gap on a campaign spending £80,000 a month matters more than a 2x gap on one spending £400. When you do move a target, move it 5 to 15% at a time, a week apart, and never change target and budget in the same week or you will not know which one did what. One more trap: the Bid Target Adjustment Tool offers to reset your target to recent actual performance. Applying that blindly locks in whatever number the budget cap happened to produce, not what your business can actually afford per lead. Keep a target only if you can say out loud why that specific number is the goal.
And do not build a Q4 case on Performance Planner numbers before 31 August. Google has told you they may be wrong.
Read more: https://ppc.land/google-pushes-budget-capped-campaigns-back-up-to-target-cpa/
2. The IAB says your AI-written copy needs no label. Your AI-generated images do.
On 18 August 2026 the Interactive Advertising Bureau published version two of its AI Transparency and Disclosure Framework for advertising, replacing the version it issued in January. It is voluntary and carries no enforcement, but it is the closest thing the industry has to an agreed answer to a question creative teams are being asked constantly, which is what actually needs a label.
The test is a single question. Does the AI involvement create a material risk that consumers will be misled? Three criteria sit underneath it: deception potential, material impact, and expectation alignment.
What needs disclosing. Images generated from AI prompts, whether text to image or image to image, and regardless of how much a human refined them afterwards. AI-generated video. Synthetic voices of deceased people, and synthetic voices of living people placed in scenarios that did not happen. Photorealistic AI influencers and avatars. Digital twins of the deceased, and digital twins of living people in events that never took place. AI chatbots get a label too, though theirs reads “AI-powered” rather than “AI-generated”.
What does not. Routine post-production, meaning colour correction, lighting, background cleanup, blemish removal and contrast. Clearly stylised or fantastical imagery. Upscaling and de-noising. Internal workflows. Background music and standard audio enhancement. Generic synthetic voices, and authorised synthetic voices of real people. Obvious cartoon avatars. And, the one that will surprise most people, text and copy.
That last exemption is the whole story for a B2B team. AI-written headlines, slogans, product descriptions, email subject lines, blog posts and translations all sit on the no-disclosure list. That is precisely what most marketing teams are actually using AI for, day to day. The framework treats an AI-written subject line as a non-event and an AI-prompted hero image as something requiring a visible mark, even if a designer spent an hour reworking it.
The mechanics, if you need them. Either the Unicode sparkle at U+2728 in monochrome, or a plain “AI-generated” text label. Either satisfies the framework. Text labels need WCAG AA contrast of 4.5 to 1, plus alt text and captions. Video labels go on the first frame and persist. Audio disclosure is spoken before or immediately after, and repeated once past sixty seconds. All of it pairs with C2PA metadata carrying two new assertions. There is a 24-month roadmap and a recommendation to name an AI Disclosure Lead within 60 days.
Why it matters / what to do: This landed sixteen days after the EU AI Act’s Article 50 transparency obligations became applicable on 2 August. Article 50 requires disclosure but does not prescribe an icon, and the EU Code of Practice finalised in early June is itself voluntary with an illustrative icon that is not finalised. So the IAB framework is currently the most concrete guidance available, and it will function as a de facto standard whether or not anyone adopts it formally.
Take the list above and turn it into a one-page internal rule for your team this week, because the alternative is every designer and copywriter making the call individually. The practical shape of it: your copy is fine, your imagery is not, and refining a generated image by hand does not exempt it.
One caveat to hold onto. The IAB is the advertising industry’s trade body, and a framework that argues against blanket labelling, partly on the grounds that labelling costs clicks, has an obvious interest sitting behind it. Treat it as a well-researched industry position rather than a neutral one.
Read more: https://www.iab.com/news/updates-industry-framework-ai-transparency-disclosure-advertising/
3. Google made its visible AI watermark optional, and handed you the disclosure liability
We missed this last week, and it belongs directly alongside our own lead story, so here it is.
On 14 August 2026, Google began rolling out a setting that removes the visible watermark from content its AI models generate. It covers images from Nano Banana, video from Omni and music from Lyria. The setting lives at Settings, then Media Watermark, in the bottom left of gemini.google.com, and in the Flow video editor. Support in Google Search is described as coming soon.
What stays. In Google’s own words: “This setting only controls the visible watermark. It doesn’t affect SynthID watermarks or Content Credentials for media you create with Gemini Apps.” SynthID is the imperceptible signal Google embeds in generated media, and C2PA Content Credentials are the metadata standard attached to the file. Both remain, whichever way you set the toggle.
Availability, because this is where most coverage got it wrong. Google’s support page says: “If you are in India, South Korea, or Vietnam, you’ll only see this setting if you have an AI Ultra subscription. Otherwise you’ll automatically see visible watermarks applied to all visual media you create with Gemini Apps.” There is no EU restriction, so UK and European marketers get the setting normally. Work and school accounts are a different matter. Google is explicit that if your access comes through one, “this setting is not available and you will continue to see the watermark”, which will catch a lot of B2B marketers generating from a company Google account.
The watermark remains on by default, so this is an opt-out rather than something that changed under you. It applies only to files created after you change the setting.
How it was announced tells you something. Not through a blog post. Josh Woodward, Google’s VP for Gemini, posted it on X alongside Gemini 3.7 Flash reaching the app. The sharpest comment came from a reply under that post, pointing out that a menu item labelled “Media watermark: off” is misleading when what it means is visible off, invisible still on.
Why it matters / what to do: Read this next to the previous story and next to our own lead a week ago. The IAB has ruled that AI imagery needs a label. Anthropic has made text marking invisible and compulsory. Google has made image marking invisible and optional. The direction of travel is identical in all three cases, which is that the signal telling someone content is synthetic is moving from something a reader can see to something only a detector can read.
The practical consequence is a transfer of liability. When Google stamped every image, the disclosure was handled for you. Remove the stamp and the duty to disclose under Article 50 sits entirely with whoever publishes the asset, which is you. If a piece of generated content misleads someone, Google can point at the SynthID mark still sitting inside the file.
So decide your policy this week rather than leaving it to whoever is generating the asset. Two questions settle it. First, which account are your people generating from, because a work account keeps the watermark whether you like it or not. Second, if you do switch the visible mark off, what replaces it in your own process, given the file still carries provenance data you cannot remove and a disclosure obligation you now own.
Read more: https://support.google.com/gemini/answer/17405358
4. Reddit’s ChatGPT citations fell 86% in four days
Between 14 and 17 August, Reddit’s share of citations in ChatGPT Search fell from a 3.83% average, measured across 18 July to 7 August, to 0.52%. That is a drop of 86.4%, and it happened over a long weekend.
The contrast is the actual lesson. Reddit’s citation share in Google’s AI products barely moved over the same period, declining gradually from around 2.5% in early July to roughly 2.1% in August, with AI Mode following a similar curve. So this is not Reddit losing relevance. It is one platform changing how it sources answers, without announcement, over four days. The timing loosely coincides with ChatGPT Search changing its query fan-out behaviour on 8 August, though nobody has established a causal link.
Two caveats, and both need to travel with the number. Promptwatch, which produced the data, says plainly that it shows when the shift occurred and not why, and cannot rule out a data collection issue on its own side. Separately, and this matters: Promptwatch is owned by Semrush, which also owns Search Engine Land, the outlet that published the finding. The same corporate parent owns the measurement platform and the publication reporting on it. That does not make the number wrong, but you should know it before you quote it in a deck.
Why it matters / what to do: A great deal of the answer engine optimisation advice written this year reduces to “get mentioned in Reddit threads”. If your visibility plan leaned on that, the ChatGPT half of the payoff may have evaporated in a weekend, and you would have no way of knowing because nothing was announced.
The durable takeaway is not about Reddit. It is that citation sources are platform-specific and can change overnight with no notice, which makes any single-platform AI visibility strategy fragile by construction. If you are tracking your brand’s presence in AI answers, check that you are tracking it across more than one engine, and check that your content distribution is not concentrated in one third-party property whose standing you do not control.
Read more: https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473
1. The marketer’s AI stack that one prompt builds (Kieran Flanagan)
Published 18 August 2026 on Marketing Against the Grain. Disclosure: this is a HubSpot show, and the episode carries a HubSpot advert. The framework stands on its own regardless.
The premise is that the advice to “become a systems builder” is everywhere and almost never accompanied by an actual system. So he lays out his own, as five layers, and the ordering is the part that matters.
Layer one, intelligence. Everything else reads from here, and nothing works without it. His words: “There is no system if you do not have context, you don’t have intelligence, and your skills are reading from that intelligent context layer in a meaningful way.”
Six context files, each one a markdown document: goals, ICP (your ideal customer profile), competitors, positioning, team, and execs. Goals anchors everything to what you are actually trying to achieve this quarter. Team and execs exist so that skills built on top can handle managing your people and managing upward.
The routing detail is what separates this from a folder of documents. Skills pull only the files they need, not the whole layer. His reasoning: “Imagine a world where every skill was just told to read everything in here before executing it. That’s a really clunky thing. The skill has to hold a lot of context, it’s going to get confused, it needs to have a ton of tokens.” So the people brief reads team and goals. The voice-of-you skill reads positioning and goals. Nothing reads everything.
He puts two maintenance tools in the same foundational layer, which is unusual and sensible. The first is an AI coach, a skill you run weekly that looks across your own usage and returns four things: your three weakest prompt habits, the three skills you should build based on repetitive requests you keep making manually, the context files most in need of an update, and one capability you are not using that fits how you actually work. The second is Record a Skill, the Claude desktop feature we covered on 25 July, used here to capture how you work and turn it into a skill automatically.
Layer two, scale yourself. A people brief that assembles what you agreed at the last one-to-one, follow-ups you owe personally, their KPIs and performance against them, blockers, wins you should call out by name, and two questions worth asking that you would not have thought of. He is candid about why the wins line exists: “I’m really bad at giving people some kudos. I’m always looking for the problems.” Then a voice of you skill so colleagues can get an answer before they interrupt you, which answers from your intelligence layer rather than general knowledge, cites which files the answer came from, and states how confident it is that this is genuinely your view. That last detail is what makes it safe to use. Then a storyteller skill that turns your goals into the narrative you give execs about what marketing is contributing.
Layer three, better thinking. An exec panel built from your execs file, which you pitch to before pitching the real thing, so the holes get found in private. And a challenge me skill running structured thinking methods, including inversion, meaning “what would guarantee this fails”, and a pre-mortem framed as “it is 6 months from now and this has failed, write the post-mortem”.
Layer four, product story, which he argues is task number one for marketers right now because everything sounds the same. A voice of the customer built from your ICP file that you can interview: what are your biggest problems, what would make you happy, what about our pricing frustrates you. A voice of the competitor querying a competitors.md you update monthly with their launches, case study pages, product pages and paid messaging, so you can ask it how it is competing against you. Then an are we really different skill that takes positioning, competitors and ICP together and grades your differentiation from 1 to 10 across your website, product pages and advertising. The question it exists to answer: “Are we going to get lost in the noise?”
Layer five, run your day. A priority list built from goals, team activity, exec requests, email and Slack. A what-did-I-miss pass that sweeps email, Slack and document comments, groups them oldest first, and gives you a one-line draft reply for each. A blocker watcher that scans for people waiting on another team, a missing decision, missing budget, missing headcount, missing data, or repeated slipped dates, then tells you who is blocked, for how long, and with enough context to actually unblock them. And live artifact dashboards aggregating data across your tools.
Do this now: Build layer one only, this week. Six markdown files, written honestly, is a weekend job and it is the layer everything else depends on. Then add exactly one skill from layer five, because a daily-use skill is what makes you maintain the context files. His own warning applies to the rest: “You maybe only really need one of these. This is like pretty overbearing.” Do not build all fifteen skills. Build the intelligence layer properly and one thing that reads from it.
Watch more:
2. Claude Code as a one-person marketing team, with the real costs attached (Nate Herk)
Published 21 August 2026, 38 minutes, and the most complete end-to-end build of the week. He uses a fictional brand, a canned protein coffee called PerkForm, and generates every asset live. Disclosure: Higgsfield is the paid tool at the centre of this and the video is structured around it, so read it as commercially interested even though no sponsorship is declared on air.
It starts with a framework, not a tool. The three Ps: Pain, Person, Promise. What is the pain, who specifically feels it, and how does your product promise to solve it for them. His reason for insisting on this first: “You need all this stuff to make sure that your marketing assets don’t look and feel like generic AI slop. They have to have a purpose. They have to have intent behind it.”
The setup, step by step. Create an empty folder on your desktop. Open Claude Code desktop, sign in, start a new chat, click open folder, select it, and hit trust workspace. Despite the name, there is no coding involved. His framing: “Just because it has the word code, don’t think that we’re going to be coding. The reason why we’re using Claude Code is because Claude Code works out of directories, out of projects.”
Then you dump your business context in and ask Claude to build the project structure. What came back: a CLAUDE.md as the operating document telling every future session what to load, a /context folder holding brand positioning, customer avatar, product facts, voice and copy, a message bank, playbooks and competitive landscape, plus an empty /assets folder and an empty /output folder. The CLAUDE.md itself is short, essentially “this is the project, Nate owns this business, read these files before writing anything”.
A tip worth stealing if you struggle to articulate your own business. He uses a skill he calls grill me, which is just a markdown file whose instruction is to relentlessly interview you about a topic until you reach shared understanding. You drag it into the chat, ask Claude to install it, then run it on your product and marketing. It interviews you question by question and saves the result as context.
Connecting the image and video generation. Higgsfield aggregates multiple models under one subscription, including Seedance 2.5 for video, GPT Image 2 for images, plus Kling, Nano Banana and others. To connect it: in Higgsfield, go to MCP and CLI at the top, copy the Claude URL, then in Claude go to Customize, Connectors, Add custom connector, paste the URL, name it Higgsfield, add, connect and sign in. Higgsfield’s own documentation confirms these steps and confirms it works with Claude on web, in Cowork and in Claude Code, with no API keys to manage.
The debugging habit is the most transferable thing in the video. When he dragged a folder of product shots into the project, the sidebar displayed it oddly and he could not tell whether Claude could actually read the files. Rather than guessing, he asked: can you see all the product shots inside that folder, there should be eleven. Claude read them and returned the inventory. His advice, and it applies well beyond this workflow: “when you’re in a situation like this where you’re a little confused, just ask Claude what it sees.”
What it produced, and what it cost. He fired four prompts in the same session, each specifying the goal, the brand context to use, where to save the output, and a request to report the cost.
Eighteen ad creatives for a buy-one-get-one offer, on brand, using the colour scheme and typography from the guidelines PDF, some deliberately left blank for copy to be added later. Cost: $3.43. His own note on this: he gave it almost nothing to work with. “I literally just said, hey, create me some ads for BOGO. If you’ve been running ads for a while, then apply that subject matter expertise to your prompts and it will be even better.”
A sizzle reel in vertical and landscape, built through Higgsfield Marketing Studio with music, scene changes and edits. Cost: $17.55.
Five Instagram carousels of seven to eight slides each, consistent across the set. Cost: $9.56.
A set of UGC-style video ads, the most expensive of the four, and structurally the most interesting. Claude generated four consistent creator characters as images first, then storyboards for each, then video from the storyboards, then ran a quality assurance pass on its own output, screenshotting frames, rejecting generations with faults it spotted, and only then reporting finished.
He is honest about where it falls short, which is worth quoting because most videos of this type are not. On the UGC output: “they are still very like ad like, they’re very salesy in a way. You can tell it’s not completely organic.” His suggested fix is to have it analyse real UGC first, or write and approve scripts yourself before generation. And on the whole exercise: “you can’t just expect to throw one prompt out there and then go viral and go make a million dollars.”
The last step turns this from a generator into a system. He asked Claude to build a spreadsheet tracking every generation: date, generation type, campaign, channel, primary angle, angles covered, deliverables, number of generations, tool and model used, credits consumed, actual cost, and status. Plus tabs for creative assets, angle performance, a copy bank and a cost summary. It took about eight minutes and it used the brand guidelines to style itself. Once that exists, performance data can flow back in, and you can ask it which angles worked before commissioning the next round.
Do this now: Spend an hour on the folder and the context files before you generate a single asset, because that is the whole difference between branded output and generic output. Then run one small job with a cost report attached to the prompt, so you learn what your own volume actually costs before you commit. And build the tracker early rather than late, because eighteen creatives across four campaigns becomes unmanageable in a folder within a month.
Watch more:
3. Wiring Claude into Search Console and Analytics in under ten minutes (Eliot Prince)
Published 15 August 2026. Seven minutes long and it solves a problem a lot of people have hit: Claude has no native Google Search Console or Google Analytics connector, and browsing the connector directory will not turn one up.
The middleware is Composio. Note the spelling, because automated transcripts of this video mangle it badly. It is Composio, at composio.dev, and it connects Claude to a large catalogue of applications through the Model Context Protocol.
Step one, set up Composio. Create an account and log in. Before doing anything else, check that “For you” is selected in the top left, not “Platform”. He is emphatic about this, and the reason is that the platform view is the developer-facing side and will send you down a much more complicated path than you need.
Step two, connect the two Google properties. Go to Connect Apps, search for Google Search Console, click connect, and complete the authorisation. Repeat for Google Analytics. You can connect multiple accounts, or a single account holding all your properties, which is the useful configuration if you manage several client sites.
A gotcha the video skips, which is worth adding. Composio’s own documentation and other walkthroughs flag that during the Google authorisation step you must tick every permission box, particularly the ones granting the ability to view and manage analytics data. Miss one and the agent will see the account listed but will be unable to pull any reports, which produces a confusing failure that looks like a broken connection rather than a permissions problem.
Step three, connect Composio to Claude. Copy the Composio MCP server URL. In Claude, go to Customize, then Connectors, then Add, then Add custom connector. Paste the URL into the second field, give it a name, and ignore the advanced settings entirely. Click add, then click connect, and complete the authorisation back to your Composio account.
Step four, and this is the bit people get stuck on. You have to name the tool explicitly in your prompt. In his words: “You have to tell it which app you want it to actually pull from through Composio.” So the request looks like: get me the overview stats from Google Search Console for the last 30 days, through Composio, for this domain. His own fix for the repetition is to save a memory rule so that any Search Console request routes through Composio automatically.
What it returns. He asked only for thirty days of overview data and Claude volunteered the analysis unprompted, flagging that traffic was dangerously concentrated, that desktop was the weak spot, and that click-through rate had collapsed. He then asked it to build a live artifact dashboard from the same data with action points, styled to his brand. He keeps a version pinned in the sidebar covering several sites, refreshing on a schedule.
Do this now: Do the connection itself, which genuinely takes about ten minutes, then resist the urge to build a dashboard immediately. Ask it one real question first, something you would otherwise export a CSV to answer, such as which pages lost the most clicks month on month and what they have in common. The value here is not the dashboard, it is that your SEO data becomes something you can interrogate in the same place you write.
Watch more:
1. Meta AI can now analyse and optimise your Meta Ads campaigns
Announced 20 August 2026, and positioned as a small business feature. You connect your Meta ad campaigns to Meta AI and it analyses performance, recommends changes and produces decks, documents and spreadsheets from the results. The part that deserves a pause before anyone clicks through the setup is that it also connects to Google Workspace, meaning Gmail, Docs, Sheets and Slides. Connecting your company email and document store to Meta’s AI is a procurement and data governance decision, not a toggle a performance marketer should flip on a Tuesday afternoon. Worth evaluating on the ads side, worth routing through whoever owns your data policy on the Workspace side.
Read more: https://searchengineland.com/meta-ai-can-now-analyze-and-optimize-meta-ads-campaigns-485588
2. Google Demand Gen view-through optimisation goes video-only, and switches itself on
From 17 August, view-through conversion optimisation in Demand Gen became video-only, with image asset view-throughs demoted to secondary conversions. Two details make this more consequential than the headline suggests. It is enabled by default on all new Demand Gen campaigns, so you have to opt out rather than in. And it expands beyond YouTube and Discover onto the Display Network, where Display video assets move from CPC to CPM billing regardless of whether you use view-through optimisation at all. A billing model change combined with a default-on setting is exactly how a quarter’s numbers move without anyone noticing until the reporting lands.
Read more: https://searchengineland.com/google-updates-demand-gen-view-through-conversion-optimization-485127
3. Gmail’s domain reputation score is now actually gone
Confirmed on 21 August, and this is an ending rather than an announcement. Postmaster Tools v1 has finally shut down, the old interface link no longer works, and the Domain and IP Reputation charts have disappeared. The deprecation was announced back in 2024 and v1 was officially retired in September 2025, so the correct framing is that the thing you were warned about has now happened rather than that Google just did something. What replaces it is a Compliance Status dashboard mapped requirement by requirement to Gmail’s bulk sender rules, plus a Deliverability Analysis added in June 2026 that returns a plain-language verdict, including two outcomes that are not failures: not enough volume to determine, and recipients appear to want more of your messages. The buried detail worth the whole entry: Google’s published sender guidelines still cite 0.3% as the spam complaint ceiling, but the v2 API’s failure code is defined at 0.1%. Both thresholds are live simultaneously, checked by different systems, so a sender can be compliant with the published guideline and still receive a negative verdict. Treat 0.1% as your internal alarm. Note that the 0.1% figure is observed behaviour reported by deliverability vendors rather than published Google policy.
Read more: https://www.mailgun.com/blog/deliverability/gmail-reputation-data-is-dead-now-what/
4. Google changed how Branded Searches are measured, and dropped Performance Max
A documentation update on 18 August rather than a new feature, but it changes numbers you may already be reporting. The default conversion window is now seven days, down from a thirty-day view-through window, adjustable between one and thirty days. More importantly, the eligible campaign types are now listed as YouTube and Demand Gen only, and Performance Max no longer appears. It sits under the Consideration goal, remains reporting-only rather than a bidding target, and shows up in Results and All Conversions rather than Conversions. If Branded Searches out of Performance Max appears anywhere in your reporting, check this week whether it still exists.
Read more: https://searchengineland.com/google-updates-branded-searches-conversion-measurement-485353
5. Informa TechTarget launches a free B2B AI Authority Index
Released 17 August, a 24-question self-assessment scoring how likely your brand is to be recommended by AI systems during a B2B buying process. It places you in one of four archetypes: The Newcomer, The Contributor, The Referenced, and The Authority. It comes with a companion white paper. Set expectations correctly: this is a diagnostic lead magnet rather than research, and Informa TechTarget sells B2B media and intent data into precisely the gap it identifies. That said, twenty-four structured questions is a reasonable free way to force a conversation about AI visibility with people who have not had it yet, particularly if you need something to put in front of a sceptical stakeholder.
6. Google AI Max gets cross-campaign testing, and keeps your guardrails on
Announced 20 August, with the headline feature arriving in September. From then, a single A/B test can span multiple Search campaigns at once with different budgets and return-on-investment targets, which finally matches the level most B2B accounts actually budget at rather than forcing single-campaign tests. The quieter improvement is available sooner and matters more: AI Max experiments can now run with brand and location controls left enabled, so you no longer have to strip out your guardrails in order to measure the thing you are testing. Performance Planner also gains the ability to forecast bidding and budget changes and apply the recommendation in one click, though see the top story before trusting its numbers this fortnight.
Read more: https://searchengineland.com/google-adds-new-ai-max-testing-and-planning-tools-485566
7. Perplexity Computer now runs from your inbox
Shipped 18 August. You can send, forward or copy in computer@perplexity.com to trigger a full Computer agent task without leaving your email client, and the finished work comes back in the same thread. It is the lowest-friction delegation pattern any vendor has shipped so far, because it requires no new tool for anyone to adopt and no change to how a team already works. Two caveats. It needs a plan that includes Computer, and no independent testing has appeared yet. More importantly, emailing an agent means emailing your content to a third party, so the same governance question applies here as with the Meta AI entry above.
Read more: https://www.perplexity.ai/hub/blog
1. Only 11% of brands appear across all three major AI models
Published 18 August 2026 by Fractl, and it is the rare AI visibility study that publishes its full methodology. 96 industry-specific prompts, each run 15 times across three models, producing 4,320 responses and more than 8,500 unique brand references, then mapped against Ahrefs domain authority, organic traffic and keyword rankings.
The headline finding is that traditional search authority and AI visibility align for over 90% of brands, which is reassuring and slightly dull. The number that should change what you do is the split beneath it: only 11% of brands appeared across all three models, while 77% appeared in just one. Roughly 5% were underexposed despite strong SEO, and about 4% overperformed in AI answers on modest traditional signals.
What to do: If you are measuring your AI visibility on a single platform, and most tools default to one, your reported position is systematically overstated. Three quarters of brands are visible in exactly one place, which means a single-engine check will tell most companies they are doing fine. Add a second and third engine to whatever you are tracking before you report a number to anyone. Disclose in passing that Fractl sells digital PR and content distribution, which is the remedy the study implies.
Read more: https://martech.org/ai-visibility-index-shows-which-brands-are-disappearing/
2. Meta is now the biggest AI crawler on the web, and it sends almost nothing back
Published 18 August 2026 by DataDome, with fieldwork covering Q2 2026, so this is genuinely current rather than a recirculated older study. 17.7 billion AI agent requests, up 45% on Q1.
The growth did not come from where you would assume. Neither Google nor OpenAI drove it. Meta-ExternalAgent grew 74% quarter on quarter and Meta-WebIndexer grew 163%, and Meta’s two agents now account for the majority of AI agent traffic DataDome observes. They also return close to nothing in referral traffic.
What to do: Go and read your own robots.txt this week. Almost every AI crawler rule written in the last two years targets GPTBot and Google-Extended, because those were the names in the discourse when the rules were drafted. The largest crawler by volume is now one most policies do not mention, and it is taking content without sending readers back. Whether you block it is a strategic call rather than an obvious one, but making that call by accident because your file is eighteen months old is not. DataDome sells bot defence, so weigh the framing accordingly.
3. AI visibility reached the boardroom faster than the data to support it
Published 21 August 2026. A survey of 400 people responsible for marketing and communications at companies in the US, UK, France and Germany, spanning C-level through to manager.
The adoption numbers are striking. 54% now measure AI search visibility or brand citations in AI-generated content. 46% include AI visibility in C-suite reporting. 42% track which prompts surface their brand’s coverage. For a discipline that barely existed eighteen months ago, that is remarkably fast institutional adoption.
The tension is in what sits underneath. Only 49% are very confident in the accuracy of their data, while measurement influences strategy and budget for 88% of paid social decisions, 87% of paid media and 85% of owned content. Just 35% have fully integrated reporting and 37% are still working from manual spreadsheets.
What to do: If you are one of the 46% now reporting AI visibility upward, put a confidence caveat next to the number before someone else finds the hole in it. Reporting a metric to the board creates an expectation that it is solid, and half of the people doing it do not believe their own data. Pair this with the Fractl finding above, because single-engine measurement is one specific and fixable reason to distrust your own figures. Two caveats on the study itself: the fieldwork date is not published anywhere, which is a real weakness, and it comes from 10Fold, a B2B technology PR and communications agency that sells into exactly the gap it describes.
Read more: https://martech.org/marketers-dont-trust-the-data-used-to-shape-budgets/
1. Microsoft gutted the free Copilot tier on 18 August with five days’ notice.
Deep Research is gone for consumers, and its successor Researcher requires Microsoft 365 Premium at $19.99 a month, which Personal at $9.99 and Family at $12.99 do not include. Copilot Podcasts were retired entirely along with the back catalogue, Group Chats converted to one-to-one with other participants’ contributions becoming unreachable, and Copilot Labs wound down.
2. ChatGPT Ads switched automatic advanced matching on for existing web pixels on 17 August, and the opt-out window has closed.
It applies to any account running a ChatGPT web pixel, so a test campaign from the spring that nobody has touched since turned itself on. You can still reverse it per pixel via Tools, Conversions, Data Source, Edit pixel.
Read more: https://ppc.land/chatgpt-advertisers-face-10-days-to-opt-out-of-automatic-advanced-matching/
3. From 24 August, YouTube counts a view from the first frame of playback across Shorts, long-form and live.
Public view counters will climb faster as a result. Partner Program earnings and eligibility are unaffected.
Read more: https://ppc.land/youtube-makes-a-view-an-impression-across-all-formats-from-august-24/
4. Google Ads API v25.1 landed on 19 August
with 24 new Conversion Lift metrics, brand lift dimensions on an allowlist, category-scoped benchmarks with share of voice, and brand sentiment for creators. The quietly useful addition is original_conversion_value, which shows conversion value before Google’s own value rules adjust it.
Read more: https://searchengineland.com/google-ads-api-v25-1-expands-measurement-and-insights-485535
5. Google is testing Enhanced Matching for Customer Match,
Spotted on 19 August as an unchecked opt-in setting that would expand list reach by matching your consented first-party records against consented users from publishers. This was found in a screenshot rather than announced, Google has not confirmed it or named any participating publishers, so treat it as a test in the wild.
Read more: https://searchengineland.com/google-ads-tests-enhanced-matching-for-customer-match-485490
First, provenance moved this month from something a reader can see to something only a machine can read, and nobody put it that way out loud.
Anthropic began marking everything Claude writes with an invisible watermark, worldwide and with no way to switch it off. Google made its visible watermark optional while leaving SynthID and C2PA embedded regardless. The IAB ruled that AI-written copy requires no disclosure at all, while AI-generated imagery does even after a human reworks it.
Three separate organisations, three different mechanisms, one direction. The signal that content is synthetic still exists in every case, and in every case it has become less visible to the person actually reading it. What that transfers is responsibility. When the label was automatic, the platform carried the disclosure. Now the file carries a mark that only its maker can detect, no third party can verify, and the publisher is left holding the legal obligation. Anthropic’s own detection interface still does not exist, and the EU deadline that forces it out is 2 December.
For a marketer the practical question is no longer whether to disclose AI use, because the regulation already answers that. It is whether your team knows which outputs carry an obligation, and right now the honest answer in most organisations is no.
Second, an entire measurement category appeared in a single fortnight, and every company selling it also sells the cure.
Five vendors shipped AI visibility measurement products on 20 August alone, with Cloudflare and Microsoft doing the same the week before. Meanwhile Fractl found that 77% of brands appear in only one of the three major models, DataDome found that Meta quietly became the largest AI crawler on the web while returning almost no traffic, and 46% of marketing leaders are already reporting AI visibility numbers upward while only half of them trust the data underneath. That combination is worth naming plainly.
Demand for the metric has outrun the ability to measure it, the tools filling the gap were built by companies with a commercial interest in the answer being alarming, and the numbers are now reaching boardrooms. This is roughly where social media measurement sat in 2011, and the lesson from that period is not that the metrics were worthless. It is that the people who did well were the ones who wrote down what they were measuring and why, before a vendor wrote it down for them.
REMINDER: MY BEST BUNDLE YET FOR MARKETERS:
For marketers who want their hours back. The full Operator System, the Setup Skill that builds your working environment, and 5-Minute Slides, together for the first time. $250, everything included. (Individual price $953).
Tell me: What’s your biggest takeaway from this weeks news from the world of AI Marketing? Love to hear your thougths in the comments.
Thanks for reading the Marketing with AI Weekly Roundup! If you enjoyed this read, the best compliment I could receive would be if you shared it.
The Branded Searches change dropping Performance Max from eligible campaign types deserves more than a footnote — plenty of retail accounts use that metric specifically to defend PMax budget against "it's just cannibalizing brand demand" pushback from finance, and losing it from Conversions reporting quietly pulls the data backing that argument. On the Demand Gen view-through point, we're already seeing accounts with heavy product carousel usage get caught off guard by the CPM shift on Display image assets, since most budget models still assume CPC held across formats. Worth pulling both into whatever baseline export people are running this week, because they'll surface in Q4 planning long before anyone traces the discrepancy back to an August documentation update.