

Welcome to issue #47 of the Marketing with AI Weekly Roundup. Published every Sunday, it shares the top stories, playbooks, data and quick hits from the world of Marketing with AI over the last 7 days.
Subscribe to receive the week's most important AI marketing stories direct to your inbox.
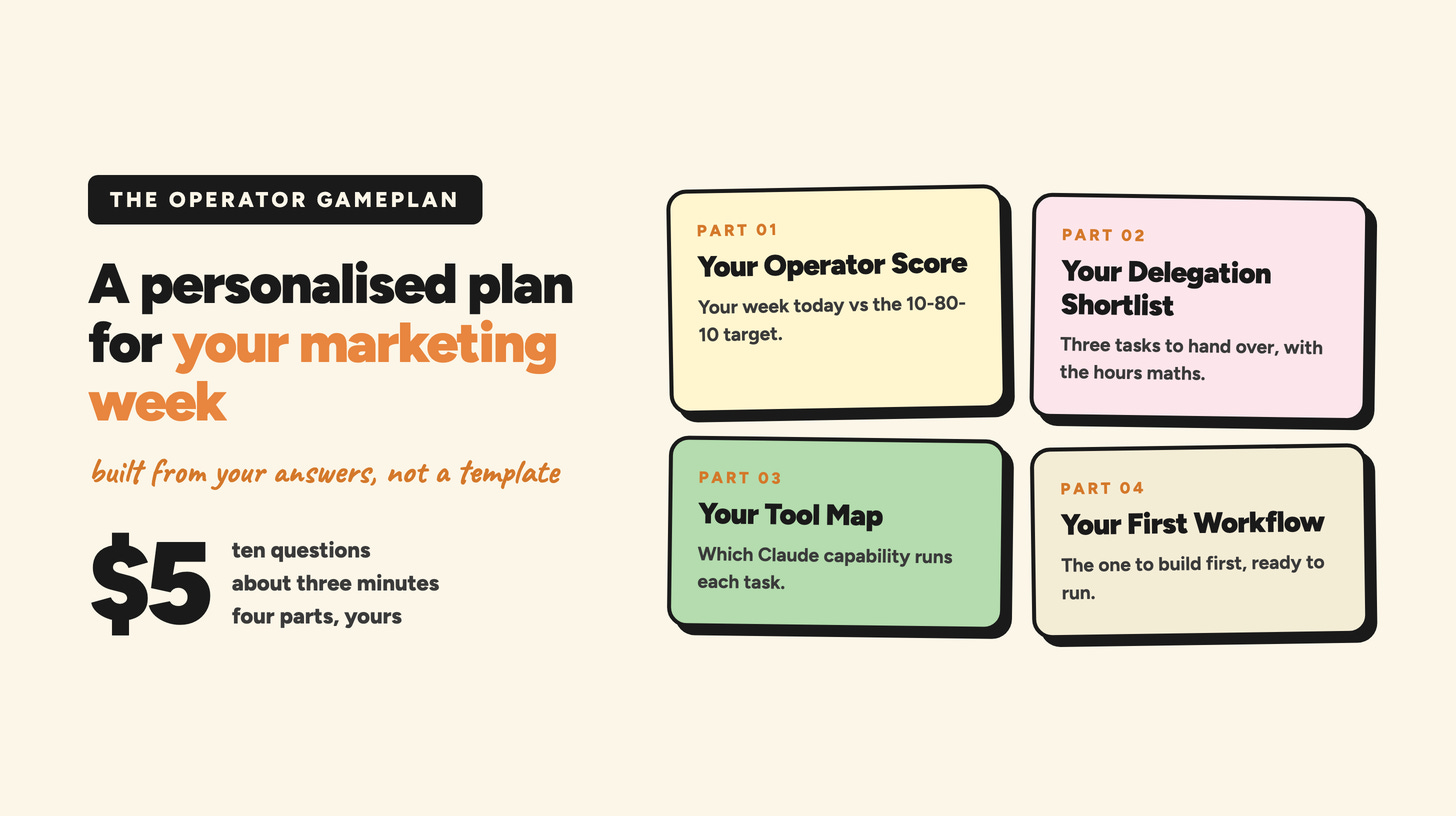
NEW: Over the last 6 months, I've asked 2000+ marketers I’m about to train the same question: where could AI save you time? I’ve now turned the data from those answers into a tool that tells you where you too can save time with AI based on your working week.
Get a personalised plan now for your marketing week, built from your answers. 👇
Last week was about what your numbers will say and what your job will look like.
This week is about proof: who can tell where your content came from, and whether the machines reading your website are being shown the same thing your buyers are.
On Friday, Anthropic confirmed it is marking everything Claude writes with an invisible watermark, worldwide, at the model level, on every surface it ships.
On Tuesday, LinkedIn published its first proper guide to getting cited in AI search, and the headline finding is that three quarters of the LinkedIn citations appearing in AI answers come from individual people rather than company pages.
And on the same day, Perplexity blocked Time magazine’s machine-only advertising and called it deceptive, less than a fortnight after we flagged the format here.
Elsewhere, Google quietly gave you control of your own attribution window for the first time, three separate datasets landed on the same uncomfortable conclusion about AI referral traffic, and the creator who runs the most-watched practical AI channel of the week deleted all his skills to see what would happen.
Below: four stories to act on, three workflows worth stealing, and the clearest evidence yet that the number in your analytics is not the size of the effect.
Let’s get into it…
1. Anthropic is now watermarking everything Claude writes, and it follows the text into your CMS
On 14 August 2026 Anthropic published the detail of how it marks AI-generated content. Every Claude model launched on or after 2 August 2026 carries an invisible, machine-readable watermark in its text output from day one. Models released before that date are being retrofitted over the coming months.
This is not a product feature, it is a property of the model. The mark applies across Claude.ai, the Claude Platform API, Claude Code, Claude Cowork and Claude Tag, and wherever Claude is offered through cloud partners including AWS, Google Cloud and Microsoft Foundry. Anthropic’s own framing is that the mark “will be present no matter which Claude product or surface the text comes from.” There is no opt-out, no extra tokens and no extra cost.
How it actually works, because the mechanism matters for what it can and cannot do. It uses Google DeepMind’s SynthID-Text method, published in Nature in 2024. It does not insert invisible characters or hidden metadata. Instead, when the model is choosing between several equally valid next words, it uses a cryptographic key plus the preceding words to settle which one to pick. The text reads identically. Anthropic says there is no practical impact on quality or content.
What survives and what does not. The mark travels with the text when you copy and paste it into a document, a CMS or an email. Anthropic says it “may persist through some editing” but has not defined how much editing that covers. It is not reliably detectable when content is heavily edited, paraphrased, translated, mixed with human writing, or simply too short. Images get C2PA content credentials instead, which is signed metadata rather than an embedded watermark. Code gets minimal marking, mostly in comments where there is arbitrary choice.
The part everyone will get wrong. Detection requires a cryptographic key that only Anthropic holds. A detection API is described as forthcoming with no date attached. Anthropic’s own limiting statement is the sentence to hold onto: detecting a mark “tells you that the content may have been processed by Claude. It does not, on its own, confirm the full provenance of the content.”
The trigger was the EU AI Act’s Article 50 transparency obligations, which took effect on 2 August. Anthropic chose to roll the response out globally rather than scope it to Europe.
Why it matters / what to do: a watermark in your draft is not a penalty, not a search signal and not a detector pointed at you. No search engine has said it reads this mark, and Anthropic has not said it hands the mark to third parties for ranking or moderation. It is a provenance signal that exists at the point of generation, inside a tool you control. So do not spend the week hunting for a way to strip it.
Do three things instead. First, if you have a client-facing or public AI disclosure policy, update it now, because a technical provenance signal exists where one did not before, and the honest version of your policy is easier to write today than to retrofit after a client asks. Second, make the substantive editorial pass a required step rather than optional polish, meaning restructured sections, added sourcing and a real fact-check, not a synonym swap. Detectability drops as a side effect of that work, but the reason to do it is that original data, direct quotes and a specific point of view are what separate a page worth reading from a page that summarises what already exists. Third, ignore any tool claiming to detect Claude’s watermark until Anthropic publishes its own documentation, because without the key nobody outside Anthropic can do it.
Read more: https://www.anthropic.com/news/claude-text-watermark
2. LinkedIn published its own AI search playbook, and it says your people are worth more than your company page
On 11 August 2026 LinkedIn published its first substantial guide to B2B visibility in AI search, written by Davang Shah, its VP of Marketing. This is first-party guidance from the platform, not another consultant’s teardown, which makes it the most quotable thing published on the subject this year.
The number that should reorganise your plan: 75% of LinkedIn citations appearing in AI answers come from individual member profiles, not company pages. That figure is Meltwater’s 2026 research rather than LinkedIn’s own measurement, and LinkedIn is repeating it in its own guide. Alongside it: articles generate roughly 60% of LinkedIn content citations, with posts accounting for the other 40%.
The supporting numbers are worth carrying because they set the stakes. 94% of B2B buyers now use generative AI for research (6sense). Gartner still forecasts a 50% decline in traditional search volume by 2028. LinkedIn’s own non-branded search traffic is down 60%. Profound puts the median time for a new page to earn its first citation at 6.81 days, with 90% of pages taking up to 37 days. And eMarketer found only 34% of B2B tech marketers feel prepared to execute an AI strategy.
LinkedIn calls the model a credibility stack: executive thought leadership, employee advocacy, third-party media coverage and contributed articles, partnerships with niche creators, and consistent reinforcement of the same core themes across all of it.
The useful part is that it comes with actual specifications, which is rare in guidance like this:
● Pick 3 to 4 core topics to own, and build clusters of content around each one rather than posting across everything.
● Posts: 200 to 300 words, keywords in the opening line, structured as a question and answer.
● Articles: 800 to 1,200 words, clear headers, a TL;DR summary at the top, and a question-driven title.
● Post 2 to 3 times a week on those core topics, publish long-form articles on the priorities, and launch a newsletter.
● Activate the people, not just the page: executives, product experts and employees posting regularly.
It also splits measurement into three tiers, which is a more honest structure than most vendor dashboards offer. Leading indicators move quickly and tell you little on their own: impressions, reactions, comments, shares. Outcome metrics move slowly and are what you actually report: citation counts, share of voice, citation rank, sentiment. Diagnostic patterns tell you what to change: which formats get cited, which authors get cited, which prompt types surface you.
Why it matters / what to do: most B2B teams have spent two years optimising a company page that, on LinkedIn’s own numbers, generates a quarter of the citations their people do. Action for this week: pick your three named experts, give each of them one of your core topics, and get one 800 to 1,200 word article published under a personal profile rather than the brand account. If you only do one thing, make it that, because the article format is doing 60% of the citation work and almost nobody in B2B is publishing them.
One caveat worth stating plainly. LinkedIn has an obvious commercial interest in concluding that the answer to AI search is posting more on LinkedIn. The specifications are still useful, and the 75% figure comes from Meltwater rather than from LinkedIn’s own data, but read the guide knowing who published it.
3. Google Analytics will finally let you set your own attribution window, and B2B has been quietly punished by the old one
On 14 August 2026 Google Analytics replaced its fixed preset lookback windows with custom ones. Click-through conversions can now be set to any value from 1 to 90 days. Engaged-view conversions can be set from 1 to 30 days, having previously been locked at three. The settings live under Advertising, then Conversion management, then Settings, and in linked Google Ads conversion management.
This is the least dramatic story in this week’s issue and probably the one that changes your reporting most.
Why it matters / what to do: if your sales cycle runs 90 days and your attribution window has been sitting at 30, you have been systematically under-crediting every campaign that starts a deal and over-crediting every campaign that happens to be running when it closes. That is not a rounding error, it is a structural bias in favour of bottom-of-funnel activity, and it has been quietly shaping budget decisions in B2B accounts for years because the setting was not adjustable.
The action takes about twenty minutes and needs your CRM rather than your analytics. Find your actual median time from first touch to closed-won, not your average, because a handful of very long deals will drag an average somewhere useless. Then set the click-through window to match that median. Then, and this is the part people skip, write down what your reporting looked like before you changed it, because the numbers will move and in six weeks you will want to know whether the campaign genuinely improved or whether you simply started counting differently.
One caveat: Google did not state whether the change applies retroactively to historical data, and we could not confirm it either way. Assume it does not until you have checked your own account, and do not present a before-and-after to your leadership until you know.
Read more: https://searchengineland.com/google-analytics-adds-custom-conversion-attribution-windows-485014
4. Perplexity blocked Time’s machine-only ads and put a number on the punishment
On 11 August 2026 Perplexity blocked all markdown advertising from Time.com from influencing its agents and its user-facing answers. That is less than two weeks after Digiday broke the original story, which we carried in On Our Radar on 8 August.
The recap, briefly, because the mechanic is the point. Time had partnered with adtech vendor Mobian to serve a stripped, machine-readable version of its pages to AI crawlers, containing sponsored content written in the advertiser’s own marketing language that no human reader ever sees. Request the page as a browser and you get roughly 303,000 bytes of normal HTML. Request the identical URL as ClaudeBot or PerplexityBot and you get about 13,000 bytes of markdown with the sponsored material baked in.
Perplexity’s Chief Communications Officer Jesse Dwyer said the company works continuously to protect users from deceptive practices, and that publishers deploying “deceptive advertising like markdown ads” face a reputational downgrade including a hit to their trust score in Perplexity’s search index. Time declined to comment. Mobian co-founder Jonah Goodhart called the overall response “extremely positive” and questioned why Perplexity would block factual brand information, arguing that accurate real-time facts serve users better. No other AI company has publicly responded.
Why it matters / what to do: the line on serving different content to machines than to humans has now been drawn, and it was drawn by a platform rather than by a standards body or a regulator. It came with a named consequence attached to a scoring system nobody outside Perplexity can see. That is a materially different risk profile from the one that existed a fortnight ago, when this looked like an interesting new revenue line.
The action is the same one we gave on 8 August and it has got more urgent rather than less. Fetch one of your own key pages six times, changing only the user agent: a normal browser, then Googlebot, ClaudeBot, OAI-SearchBot, PerplexityBot and GPTBot. Compare the six responses. Most marketers assume this is not their problem because they are not selling agent ads, and that is exactly the assumption worth testing, because your CDN, your CMS or a well-meaning performance plugin may already be serving assistants something different from what it serves buyers. You want to discover that yourself rather than when an answer engine summarises the wrong version of your pricing page to a prospect.
Read more: https://digiday.com/media/perplexity-blocks-times-ads-served-to-ai-agents-calling-them-deceptive/
1. The three levels of AI memory, and why yours is stuck on the first one (Jeff Su)
Published 12 August, and it explains the single most common complaint marketers have about AI, which is that it forgets the brand voice you taught it last week. Disclosure: the video is sponsored by Granola and he sells a Cowork course, so treat him as an operator with a commercial interest. The framework survives that.
Level one, global memory. Account-level facts your chatbot generates automatically. In ChatGPT it lives under Personalization, then Memory, then Manage. His core insight is that this layer is deliberately kept thin, because anything saved at account level gets dragged into every future conversation, and in his words, “if something wrong lands there, it poisons everything.” So it knows your role and your writing preferences and nothing about the campaign you worked on yesterday.
You can force entries in by saying “update your memory, I have a high-stakes presentation on October 6th” mid-chat and watching the memory page update. But you have to remember to do it every time, and it still lands in the global profile where it will follow you into unrelated work.
Level two, project memory. Projects draw a boundary around one work stream, so entries can be specific without contaminating everything else. Global memory still cascades in.
His failure example is the useful part. He pasted a screenshot of a calendar invite into a project chat, and Claude read it correctly at the time. Asked a week later for the confirmed attendee list, it returned a partial one, because it had decided the names were not worth keeping. His verdict: “the AI is still the author. It decides what makes the cut.” The fix is to say it explicitly: “update project memory, John Turnip is now also confirmed to attend.”
Level three, a memory system that lives in your own files. Supported by Claude Cowork and Claude Code, ChatGPT Work and Codex, and Gemini Spark.
The mechanic is simpler than it sounds. At the start of every task the system loads one small file, a `root memory.md`, which is nothing more than a routing table of active projects. You say “I want to continue working on the X presentation”, it checks the table, routes to the folder that owns that project, reads those files and loads nothing else. He says this holds up with more than twenty active projects.
The session wrap-up ritual is the part worth stealing outright. At the end of a working session you type “I’m done with the session, let’s wrap up.” It scans the session for decisions, learnings and progress, then splits them into two lists. An input needed list that requires your approval, which in his demo meant turning a one-off correction (”don’t use acronyms in slide headlines”) into a permanent rule. And an approval exempt list of things it has already done, such as recording the edits and updating the routing table so tomorrow’s session starts where today’s ended.
The line that frames the whole thing: “everything you’ve seen so far has the same root issue. The AI is still in control. It decides what gets remembered, where it lives, and when it gets written.”
His own honest caveat is that level three “does take some real effort to set up, and they work differently than the chat window you might be used to.”
Timely addition he could not have included. OpenAI shipped a related change on 14 August: an existing unshared project can now be switched between default memory and project-only memory without starting over, via the three-dot menu, then Project settings, then Memory. If you have a project that has been quietly absorbing your global memory, that is a two-click fix.
Do this now: create a single `root memory.md` listing your three live projects and the folder each one owns. Then end your next working session with “I’m done with the session, let’s wrap up” and see what it proposes to remember. The test of whether it worked is opening a fresh session on Monday and asking “where are we on the Q4 campaign and what is next”, then seeing whether the answer is correct.
Watch more:
2. Delete your skills, then rebuild only the ones that were doing formatting (Nate Herk)
Published 12 August and the highest-viewed practical video of the week. Worth being straight with you: we flagged the underlying idea on 25 July in On Our Radar, when Anthropic’s Thariq Shihipar wrote about carefully written instructions working against you. What is new here is a working test attached to it, plus an instruction on camera that the blog post never gave.
The instruction comes from Boris Cherny, the creator of Claude Code, interviewed at Y Combinator’s Startup School. Quoted directly: “for people that aren’t building agentic products, but you’re using Claude Code, every 6 months delete your Claude MD. Delete your skills. Delete your hooks. See what the model does and it might surprise you. And actually for Opus 5, this is something we really do recommend.”
On what replaced prompt engineering: “the skill nowadays is less about prompt engineering and more about figuring out how do you give Claude a hard task that seems a little bit too hard. And then how do you make it possible for Claude to verify its work along the way. And the verification, I think, is probably the single most important thing that people do not get right.”
The test is what makes this actionable. Herk duplicated his setup, stripped out his instruction file and every skill, and gave both versions the same job: turn a YouTube interview into a resource guide.
● With skills: nine pages, properly formatted, brand header image, channel links, correct colours. Structurally exactly what he had specified.
● Without skills: messier, no header, no branding. But it broke the content into ideas with timestamps entirely on its own, which he preferred. His words: “arguably I like the content of this version better.”
The conclusion to build on: keep the instructions that specify look, brand assets and constraints. Delete or loosen the ones that dictate the thinking. He would rewrite his skill as “make the resource guide however you see fit, but put this image in the header and link to my channel at the top.”
His own caveat is good editorial hygiene and we are running it: “you should probably be taking advice from people who are using the AI systems the same way you want to.” Cherny designs agent harnesses and works across enormous code bases. A marketer producing research, documents and deliverables should not blanket-apply his advice.
Do this now: take your single most-used skill or custom instruction set. Copy it. From the copy, delete every line that tells the model how to think, and keep every line that tells it what the output must look like. Run both on the same brief and compare. If the stripped version thinks better, you have been paying for formatting with your quality.
Watch more:
3. Give Claude a shared whiteboard it can actually draw on (Blazing Zebra)
Published 9 August. The problem it opens with is one every marketer recognises: ask an advanced model a simple planning question and you get back “14-page essays for even doing the simplest thing.” The fix is an editable, infinite whiteboard that both you and Claude can read from and write to. Disclosure: his prompt cheat sheet sits behind a Patreon, though the setup is described fully in the video.
Setup. Open the Claude desktop app, switch to Cowork, point it at a new empty folder. The setup prompt asks Claude to get TLDraw running locally with a file-backed bridge so both parties can read and write to JSON files, and specifies that it “should be only about 40 lines of code.” It runs on localhost. Test it by writing something on the board and asking Claude to read it. In his demo, Claude replied on the board itself.
Then drop your messy source material into the same folder, so PDFs, emails, call transcripts and documents, and tell Claude to get familiar with it.
The sequence of requests, each of which maps onto a real marketing job:
1. A mind map of the project and its major work streams. His steering phrase is worth borrowing: “keep things as simple as possible, but no simpler.”
2. A dependency map from today to the launch date, showing the critical path and anything blocking it. Blockers render in red.
3. Change one date and ask it to update the critical path. Everything downstream turns red, which is the moment the diagram earns its keep.
4. A Kanban board: “take that task CSV and build it out as a Kanban with the owner’s initials on each card.”
5. Move the cards yourself, then say “I made some changes directly to the board, tell me what changed and replan anything that needs replanning.”
6. A confidence heat map colour-coding how sure Claude is about each item, which you can then overrule.
7. Per-stakeholder versions: share, download, export to PDF, strip detail for different audiences.
Why a whiteboard rather than Claude’s usual output, in his words: “Unlike HTML, sometimes when these things build HTML, you can’t get in there and manipulate that. You have to use the AI to manipulate it.”
Do this now: if you have a campaign launching in the next quarter, build the dependency map first and then move one date. Watching the critical path recalculate in front of you is the fastest way to find out whether your launch plan was ever real.
Watch more:
1. Ahrefs launched Letaido, an agent workspace that keeps running after you close the tab
On 12 August Ahrefs launched Letaido, a separate always-on workspace where agents run multi-step jobs, build dashboards and reports, monitor your site and your competitors, and execute recurring workflows on a schedule, with native access to Ahrefs data. Integrations named at launch: Notion, Slack, HubSpot, Google Ads and WordPress. The differentiator against a chatbot is persistent hosting, meaning automations survive between sessions rather than dying with the conversation. Pricing was not published. The launch case study claims Foundation Marketing cut keyword research and bottom-of-funnel content audits from 40 hours a week to about 60 minutes, and that number is a customer quote inside a vendor press release, so attribute it as a vendor claim rather than a benchmark. Worth setting against a figure from the same coverage: 81% of martech leaders are piloting AI agents, and 45% say vendor-supplied agents have not delivered what was promised. This is the SEO tool category following Ahrefs Brand Radar and HubSpot AEO, which we covered on 8 August, into agent workspaces. The buying question is whether you want your agents living inside a vendor’s workspace or inside your own file system.
Read more: https://siliconangle.com/2026/08/12/ahrefs-launches-ai-agent-workspace-letaido-marketers-agencies/
2. Claude Cowork moved into the Chrome side panel, and took your skills with it
On 12 August the Claude in Chrome side panel became a full Cowork session. The practical change is that your existing skills, connectors and plugins now work inside the browser with no additional setup, conversations save to Claude history, and a task started in a tab can be finished on desktop, web or mobile. It can navigate pages, click, type and complete forms using the logins you already have. Live on Max and Team now, rolling out to Pro over the coming weeks, and off by default on Enterprise where admins can restrict it to approved domains. Chrome only, not other Chromium browsers, not mobile. This matters most for the tools that have no integration and never will: ad platforms, your CMS, your email service provider, vendor portals and internal dashboards. Anthropic’s own caveat is worth repeating, that browser agents remain vulnerable to prompt injection and its safeguards “cannot eliminate” the risk, so this is not the place to let it act unsupervised on anything irreversible.
Read more: https://9to5mac.com/2026/08/12/claude-cowork-chrome/
3. Google put AI agents on the front page of Ads and Analytics
Announced 10 August. Google Analytics now shows AI Overviews on the homepage summarising what changed since you last logged in, with optional email or phone notifications at a frequency you choose. Google Ads gets a redesigned homepage with personalised AI insight cards and a prompt box for questions such as how competitors are affecting your impression share, and you can click a card to route its context straight into Ask Advisor. A new Dashboards feature in Google Ads builds visualisations from a text prompt, with Analytics support described as coming soon. Ask Advisor will also now benchmark your campaigns against anonymised averages from similar businesses. Caveats matter here: this is beta, English-language accounts only, and Google’s own label on it is that generative AI is experimental. No timeline for general availability. The Monday-morning “what happened in the account last week” job is the one most B2B marketers do manually and least well, so the honest test is to ask it what changed before you open a single report, then check its answer against your own read.
Read more: https://blog.google/products/ads-commerce/google-ads-analytics-ai-updates/
4. Search Console’s generative AI report is now on effectively every account
We have covered this report twice, on 13 June when it launched and on 8 August when we warned its data was more misleading than it looks. What changed on 11 August is that the rollout finished. A pop-up now appears on the Search Console home screen pointing you at it, and it sits as an expandable tab beneath the main Performance report. You get impressions inside AI Overviews and AI Mode, separated from your normal search performance and broken down by page, country, device and date, with a matching view for Discover. You still get no clicks and no queries, and neither has appeared since June. The detail that makes this urgent rather than interesting: the data starts on 18 May 2026, nothing before that exists, and nothing backfills. Every week you do not record a baseline is a week of history you cannot recover. One honesty note: Google has not formally announced the full rollout, its help documentation still says a subset of website owners, and John Mueller has said it is not yet every domain and only appears once a site has enough AI-feature impressions.
Read more: https://www.seroundtable.com/google-search-console-ai-report-live-41850.html
1. ChatGPT referrals to B2B websites are up 303% in a year
Published 12 August from Labs by Demandbase platform data, drawn from $123 million in media spend across 75,645 campaigns. Monthly ChatGPT-referred visits to the B2B sites Demandbase tracks went from roughly 645,000 in June 2025 to 2.6 million in June 2026, with a clear inflection in May 2026 when volume more than doubled against prior months.
The competitive split is the part worth noting. ChatGPT accounts for the overwhelming majority of that growth. Perplexity referrals actually declined, while Gemini and Claude stayed flat. No conversion or engagement-quality figures were published, so this is a traffic story rather than a pipeline story.
What to do: if you are building an AI visibility programme and splitting effort evenly across four engines, this is the number that says stop. Weight your prompt testing and your measurement toward ChatGPT until your own data says otherwise. Demandbase’s own caveat is the honest one to carry: much of the activity happens before a buyer ever reaches your site, so referral counts undercount influence rather than measuring it.
2. Only 1.1% of publisher visits carry an AI referrer, and that is not the same as AI not working
Published 13 August, from a Scrunch study using a privacy-safe opt-in panel with fieldwork running February to June 2026, covering millions of searches, AI conversations and publisher visits.
AI referrals accounted for 1.1% of publisher visits. But readers were 20.5 percentage points more likely to visit a publisher in the week after a news-related AI conversation. Roughly 75% of post-chat visits arrived through direct navigation and about 9% through traditional search, meaning the visit happened but carried no AI referrer with it. Major publishers took 97% of follow-through visits while accounting for 82% of AI mentions, while mid-sized publishers had about 17% of mentions and a far smaller share of the visits.
What to do: read this next to the Demandbase number above, because the two datasets are measuring different halves of the same effect and both point the same way. Your AI referral figure in GA4 is not the size of the effect, it is the visible corner of it. The practical fix costs nothing: add a “how did you hear about us” field to your forms that names ChatGPT, Claude, Gemini and Perplexity explicitly, and compare what people tell you against what analytics recorded. Where those two numbers diverge is your actual blind spot. Caveats: this is correlation rather than causation, it measures visits rather than revenue, and Scrunch sells AI visibility software.
Read more: https://searchengineland.com/news-publisher-visits-from-ai-study-484851
3. ChatGPT is now serving ads on a quarter of commercial prompts, and one in seven misses the topic
Published 10 August in Search Engine Land, from SE Ranking’s analysis of more than 50,000 commercial prompts across 20 niches, with data collected on 23 July 2026.
Sponsored placements appeared on 25.94% of commercial prompts, putting ChatGPT close behind Google AI Mode’s 29.45% from the same research series, which we covered on 25 July. 14.35% of the ads were semantically unrelated to the prompt they appeared alongside, roughly one in seven. And in 96.37% of placements, the advertiser was not cited anywhere in the answer copy above their own ad. Advertisers also currently have no visibility into which prompts triggered their ads.
What to do: the last figure is the strategically important one and it will be missed in most coverage. Being the advertiser is not the same as being the source. In 96% of cases, someone else’s content was informing the answer while your ad sat underneath it. If you are eligible to buy ChatGPT ads at all, which most B2B readers are not yet, the earned side of that placement is worth more than the paid side, and it is available to everyone regardless of category eligibility.
Read more: https://searchengineland.com/study-chatgpt-ads-appear-on-26-of-commercial-prompts-484590
1. The IAB published the first industry standard for measuring AI visibility.
Released 3 August, “Measuring Visibility in the AI Era” is a 36-page framework built on four levels, Presence, Prominence, Portrayal and Persuasion, and it splits measurement into directional and decision-grade tiers across nine criteria, treating anything under 50 queries per programme as exploratory. It states plainly that directional data is not sufficient for budget allocation, and notes that more than 20 companies now sell AI visibility tools on methodologies that can return different answers for the same brand. Its own headline number: only 16% of brands systematically track AI visibility today.
Read more: https://www.iab.com/news/iab-releases-measuring-visibility-in-the-ai-era/
2. Google will auto-upgrade some Search campaigns to AI Max on 1 September.
An email went to advertisers on 5 August confirming that campaigns using automatically created assets or the campaign-level broad match setting will be converted. The defaults differ by trigger: automatically created assets brings search term matching and text customisation on, while campaign-level broad match brings search term matching only. To avoid it, switch the legacy setting off or enable AI Max yourself before then. Dynamic Search Ads are not part of this wave, that migration was pushed to February 2027.
Read more: https://searchengineland.com/google-to-auto-upgrade-some-search-campaigns-to-ai-max-484428
3. Three Meta Ads reports went dark on 6 August without an error message.
The device, hourly and frequency breakdowns became opt-in per ad account with Marketing API v26.0. Requests on accounts that never opted in return HTTP 200 with an empty data array, so no tool alerts you and your dashboard simply renders zeroes. The toggle sits under Additional Breakdowns in Ads Manager’s reporting view, there is no Meta help centre article for it, and both Supermetrics and Improvado issued breaking-change notices to customers. Most sources say the missing data does not backfill, so the sooner you switch it on the less you lose.
Read more: https://admakeai.com/blog/meta-ads-updates-august-2026
4. ChatGPT Atlas stops working tomorrow, 9 August.
Bookmarks, open tabs and history do not transfer automatically. Cookies and passwords can be exported to the ChatGPT desktop app and bookmarks to Chrome. It launched in October 2025 and does not reach its first birthday.
Read more: https://help.openai.com/en/articles/6825453-chatgpt-release-notes
5. Google search rankings moved sharply between 1 and 3 August,
…Picked up by third-party trackers and heavily discussed in the SEO community. As of 5 August Google had not confirmed an update and its Search Status Dashboard listed no incident. That is the fourth unconfirmed tremor since the confirmed spam update in late June.
Read more: https://www.seroundtable.com/google-search-ranking-volatility-august-1-41811.html
6. Search Console’s new generative AI performance data is more misleading than it looks.
Roughly eight weeks after the reports launched, the core problem is that the central-tendency formula treats position one inside an AI Overview as equivalent to position one in classic organic results, which distorts any trend you try to read from it. Presence metrics also arrive with no click or query detail attached.
7. A correction to something we ran on 25 July.
When we covered Claude’s Record a skill feature we flagged that Anthropic had published nothing about what happens to your recordings. That gap has now been filled by hands-on documentation rather than by Anthropic: Claude discards the raw audio and video after processing and keeps only the screenshots it needs for context, which live inside the Cowork task and disappear with it. Two details we should have carried at the time: recordings cap at about 10 minutes, and the feature is Mac only, with no Windows support and no availability on Free or Enterprise.
Read more: https://www.unite.ai/de/claude-cowork-review-record-a-skill/
8. HubSpot’s Agent Hub credit pricing has firmed up…
…closing a question we left open on 2 August. Published rates are $0.50 per resolved conversation for the Customer Agent, $1.00 per recommended lead for the Prospecting Agent, $0.10 per answer for the Data Agent, and around $10 per piece for the Content Agent. Included allowances run 500 credits a month on Starter, 3,000 on Professional and 5,000 on Enterprise, pooled account-wide with no rollover. Agent Hub itself remains free for Professional and Enterprise and is still in public beta with no general availability date.
Read more: https://www.hubspot.com/products/artificial-intelligence
9. Anthropic has added noindex and nofollow to shared Claude conversations…
which resolves the problem we reported on 2 August when shared chats began appearing in Google Search. The original cause was a robots.txt block sitting in front of a noindex header, so Google never crawled the pages to see the instruction.
10. Claude Code’s auto mode becomes the default permission setting on 14 August…
…for Pro, Max and Team users, unless a user or admin has pinned something else. It replaces repeated approval prompts with a classifier that checks each action for anything irreversible or destructive, falling back to manual approval after repeated blocks. Anthropic says it will not charge for the extra tokens the classifier uses.
First, provenance stopped being a policy question and became infrastructure.
Anthropic is now marking Claude’s output at the model level, globally, on every surface, because of a European law that took effect thirteen days earlier. Perplexity started downgrading a publisher’s trust score for showing bots different content from humans. LinkedIn is penalising AI-written comments, as we reported last week. Three different mechanisms, three different companies, one direction of travel. The question is shifting from “can anyone tell this was AI” to “can you show where this came from”, and that is a better question for anyone doing serious work, because it rewards the parts of the job that were always the point. Original data, named sources, a real opinion and a person willing to attach their name to it are not detection-avoidance tactics. They are the things that make content worth citing, and they now happen to be the things that make provenance easy to demonstrate.
Second, memory turned out to be a file-system problem, and the teams winning have already worked that out.
Six separate developments landed on the same question this week: who decides what your AI remembers. Jeff Su’s three levels, the skills that now follow you into Chrome, OpenAI letting you change a project’s memory mode after the fact, Computer History watching what you do, Nate Herk finding his instructions were constraining thinking rather than improving it, and the wider pattern of practitioners moving their context into plain files they can open and edit.
The unifying insight is Su’s, that at the first two levels “the AI is still the author”, deciding what gets kept and what gets dropped without telling you. What is striking is how unglamorous the fix is. Writing down your ideal customer profile, your pricing, your services, your team structure and your standard operating procedures is not an AI project. It is the thing you have been meaning to do for three years, and it is now the highest-leverage AI work available to most teams. This is the fourth consecutive week some version of that conclusion has appeared here, which is either a very persistent coincidence or the actual answer.
Third, the models are being handed more judgment at the exact moment marketers are downgrading their own.
Boris Cherny is telling people to delete their carefully written instructions and let the model think. Anthropic stripped most of its own system prompt. Nate Herk’s test found the unconstrained version produced better thinking and worse formatting, which is a trade most people would take.
Set that against the finding we ran on 8 August, that marketers rated critical thinking, communication, collaboration and adaptability as less important in 2026 than they did in 2025. Those are the four things the same research places furthest from automation. The uncomfortable version of this week’s news is that the industry is being told, from two directions at once, that judgment is the scarce input. One direction is telling you to stop over-instructing the machine. The other is quietly recording that we have decided judgment matters less than it used to.
Tell me: What’s your biggest takeaway from this weeks news from the world of AI Marketing? Love to hear your thougths in the comments.
Thanks for reading the Marketing with AI Weekly Roundup! If you enjoyed this read, the best compliment I could receive would be if you shared it.