
Every Wednesday, one essay on what's actually working in Marketing with AI - tools, workflows, and mindset shifts you can apply immediately.
The Marketer’s Guide to Claude Code Goals and Loops
Your email went out on Tuesday promising 20% off.
The landing page it linked to said 25%.
The social post had the old CTA, the one pointing at a page that was archived back in March.
Nobody noticed until a customer replied asking which discount was real.
None of it was badly made, though. Every asset was fine on its own. Six pieces were produced in sequence, each correct, and no one read them against each other at the end.
The mistake didn’t live inside any single content piece. It lived in the gap between them.
That’s the most common failure in marketing execution, and it has almost nothing to do with talent. It’s structural.
When work is produced in separate pieces or silos, what goes wrong is how the pieces line up, and that is the one thing not everybody checks.
AI has the exact same failure mode, and this year Claude Code got two commands that fix it.
They’re called /goal and /loop.
And unless you follow the developer world closely, you’ve probably not heard of either, because they launched as coding tools.
But they aren’t.
And they’re the most useful thing to happen to marketing execution in months, and I want to show you why.
First, why Goals and Loops is not just another feature
Think about where most of us have actually landed with AI.
You’ve learned to prompt. You write a good brief, you give context, you know a vague ask gets a vague answer.
You’ve maybe built a few Skills, set up a Project, and connected Claude to your files.
The good news…that already puts you ahead of most marketers.
But there’s a limit to prompting, and it’s easy to miss because it’s not obvious.
Every prompt, however good, gets one attempt. You ask, Claude does a pass, Claude hands back a response. If it covered eleven of your twelve points and quietly skipped the twelfth, nothing in the system notices. The response ends because responses end, not because the work is done.
The marketers pulling ahead now have made a different move.
They’ve stopped writing better instructions and started defining better outcomes.
Less “here’s what to do,” more “here’s what finished looks like, and don’t stop until it’s true.”
And this is all now possible inside Claude Code.
Not Cowork, not the chat window.
If you’ve only ever used Claude through those, this is the feature worth opening Claude Code for. I wrote a full guide to Claude Code for non-technical marketers earlier in this series, so if the name makes you nervous, start there and come back.
You don’t write code.
You describe outcomes in plain English, and that’s the whole job.
What /goal actually does
/goal is a command you type at the start of a task. You follow it with a condition, in plain English, describing what “done” means.
/goal every deliverable in this campaign uses the same offer, price and
CTA link, shown asset by asset in a table before you finish
That condition becomes a standard the work has to meet.
Claude can’t end its turn and hand back to you until the condition is actually satisfied. It produces the work, checks it against your condition, spots what’s missing, goes back and fixes it, and only stops when the thing you asked for is genuinely true.
Two details make it feel different in practice.
Typing the command starts the work immediately, so the condition is the brief and you don’t need a separate prompt. And when the condition is met, the goal clears itself, so you’re not managing anything.
That might sound like a small thing. But it isn’t, and the reason becomes clearer when you really think about it.
Every AI answer you have ever received ended for the wrong reason. It ended when the model reached the end of its response, not when the work reached the end of its requirements.
Those are two completely different finish lines, and most of the time you can’t tell them apart, because a stopped-early answer looks exactly like a finished one.
Looks finished and is finished are not the same.
A campaign where the email and the page disagree on price looks finished.
A site audit that covered nine of your twelve pages looks finished.
Three social posts where two open the same way look finished.
/goal is the difference between asking Claude to do something and telling it what done means.
Watch this 60-sec explainer video to help you better understand Goals and Loops
NB: This explainer video was created in less than 10 minutes using Claude Design...and I have no video creation skills whatsoever.
If you want to create all kinds of on-brand assets for your business, from animations to slides, brochures, diagrams, social graphics and so much more…I’ve just added a full 2-hour Claude Design training to the Claude for Marketers Masterclass to show you how.
There is genuinely a second pair of eyes
This is the part that separates goals that work from goals that frustrate you, so it’s worth thirty seconds to get clear on this section.
When Claude finishes a turn, your condition and the whole conversation so far get passed to a second, smaller model whose only job is to answer one question: has the condition been met, yes or no? A “no” sends Claude back to work, with the reason attached as guidance for the next attempt. A “yes” clears the goal and hands your session back.
So the work and the marking are done by two different models. This is the key.
The one writing the campaign is not the one deciding whether the campaign is finished, which is exactly why a goal catches things a detailed prompt doesn’t. It’s the same reason you don’t proofread your own copy.
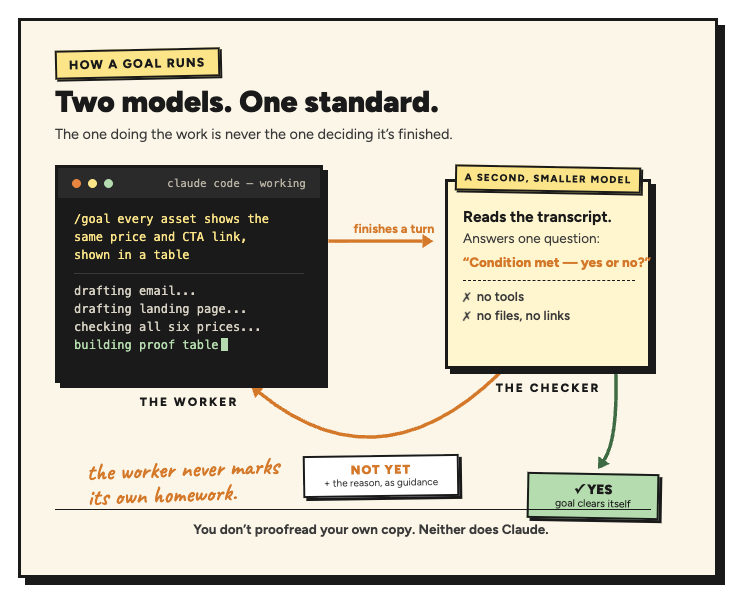
Now the single most important thing you need to understand about this checker: it cannot use tools.
It can’t open your files, run a check, or visit a link. It reads the conversation and nothing else, which means it can only confirm what Claude has actually written into the transcript.
That has one very practical consequence…
If your condition is “every link in this email works,” the checker has no way to test those links itself. It’s looking for evidence in the conversation that Claude checked them and reported back.
A goal is satisfied by visible proof, not by the work having been done.
This is why every good goal asks Claude to report, list or show its findings. It isn’t thoroughness for its own sake, it’s structurally required.
The rule to remember: state the check, not just the outcome.
Weak: “The pricing is consistent everywhere.”
Strong: “The pricing is consistent everywhere, shown asset by asset in a table before you finish.”
Same intent. The second one gives the checker something to actually read.
Prompt versus goal, and why this fixes the “80% done” problem
There’s an obvious objection here, and it’s a fair one…to a point…
If I can list twelve things I want checked, why not just put all twelve in a really detailed prompt?
You can, and it does help.
But it doesn’t solve the problem, and the reason is the whole point of this piThere’s a part in the article which creates a table look which doesn’t work in my Substack, which is the column headings say ece.
A detailed prompt still gets one attempt. Claude reads your twelve checks, does a pass, produces a response. Miss the fourth, half-do the ninth, and nothing notices.
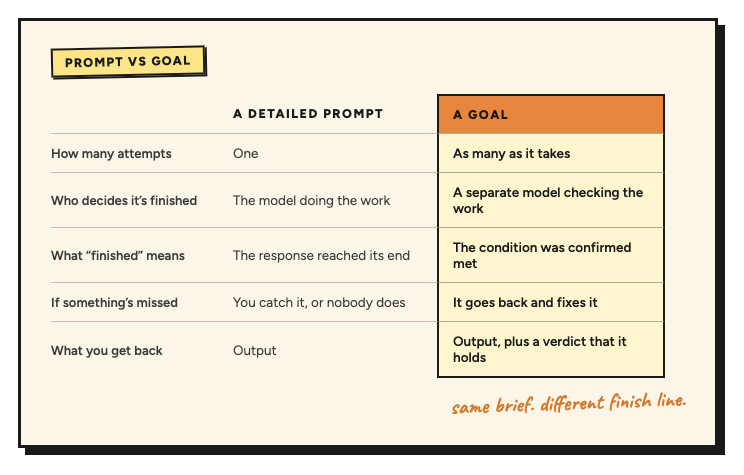
A detailed prompt tells Claude what to check. A goal makes Claude prove it did.
One marketer, Brandon Redlinger, framed the distinction better than I probably can: a prompt tells the AI what to do, a goal tells it when to stop. His blunter version is that AI bails early on prompts, but it can’t bail early on goals.
This is exactly where the “80% done” problem gets solved.
The single most common way AI work disappoints isn’t the model doing something stupid. It’s the model doing three-quarters of the job well and presenting the result with total confidence.
A goal removes the option.
It doesn’t hand you 80% dressed up as 100%, because an 80% answer fails the check and goes straight back for the missing 20%. It keeps refining until your definition of finished is actually met.
I want to be precise about “finished,” though, because it’s where people sometimes trip up. A goal drives to your checkable standard, not to some vague notion of perfect.
That distinction is the whole skill, and it’s the next section.
How to write a goal that actually works
A goal works when the checker can read the conversation and answer yes or no.
It fails when the condition is, well, just a ‘vibe’.
“The campaign is good” is not a goal. There’s no finish line, so you get either an arbitrary stopping point or Claude endlessly polishing things nobody asked it to polish.
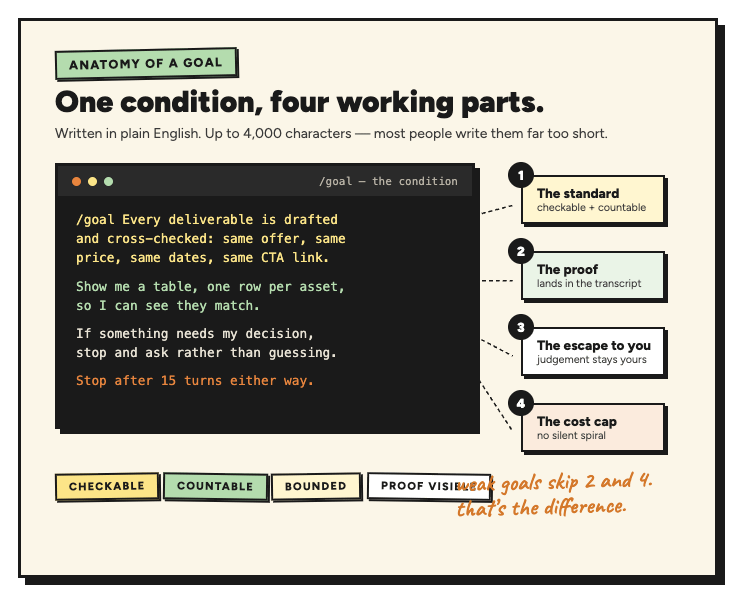
“Every deliverable uses the same offer, price, dates and CTA link, listed asset by asset” is a goal. It’s checkable, and the proof lands where the checker can see it.
Four tests before you commit to one:
1. Is it checkable? Could a stranger read the output and tell you whether the condition holds, without needing your taste or your context?
2. Is it countable? “Three drafts,” “every page,” “ten examples,” “all twelve links.” Numbers and completeness turn a wish into a condition.
3. Is it bounded? Does it have an end state, or just a direction? “Make it better” is a direction. “No page is missing a meta description” is an end state.
4. Is the proof visible? Have you told Claude how to demonstrate it, and does that demonstration land in the conversation?
You’ve got plenty of room to do this properly…
A condition can run to 4,000 characters, so a goal can carry a real checklist, not a single sentence. Most people I’ve seen using this so far write them far too short.
And ALWAYS give it an escape hatch.
Add something like “or stop after 15 turns and tell me what’s still outstanding” to the end. Without it, a goal built on something Claude genuinely can’t satisfy will keep going, and going, quietly spending money while it does. With it, you get an honest report instead of a spiral. If you take one habit from this piece, take that one.
From finishing once to improving continuously: /loop
Everything so far fixes a single piece of work. You set a finish line, Claude works until it’s reached, and you get something genuinely done rather than nearly done.
But marketing isn’t a single piece of work.
It’s the same checks, over and over, as the inputs keep changing.
New posts publish, competitors reprice, and content that ranked in January quietly drops by March. A campaign that was good to go on Monday is out of sync by Thursday as three people edit four assets.
This is where the second command comes in, and where the two of them together become more than the sum of their parts.
/loop re-runs a prompt on an interval, inside your session.
Example:
/loop 30m check the campaign folder for any asset whose offer or CTA no longer matches the brief, and flag it runs that check now, then again every thirty minutes while you work.
You can give it a fixed interval, or leave it off and let Claude choose one based on what it’s seeing, longer gaps when nothing’s changing, shorter when things are moving.
Hold the goals and lopps side by side and the benefits become clearer.
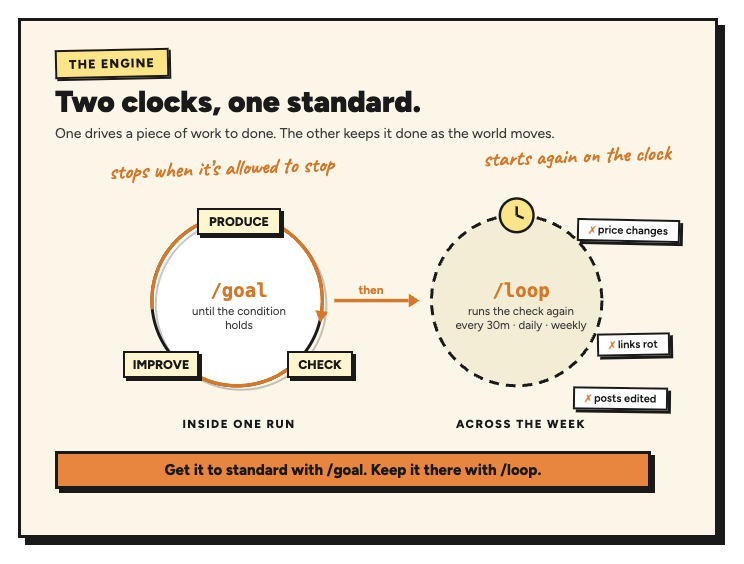
/goal controls when work is allowed to stop.
/loop controls when it starts again. One drives a piece to done. The other keeps coming back to check it’s still done as things change around it.
That’s continuous improvement.
Inside a single run, a goal already improves in a loop of its own: produce, check, “not yet, here’s why,” improve, check again, until the standard holds. Across days and weeks, /loop is the outer loop, re-running the check on a schedule so the work stays at your standard even when you’re not looking at it.
Get something to your standard with a goal. Keep it at your standard with a loop. That’s the engine.
One thing to note.
/loop runs while your session is open, so it’s for repetition you want during a working stretch: polling a build, watching a folder, re-checking a campaign as it comes together.
For a check that should run every morning whether or not you’re at your desk, that’s Routines, the cloud-scheduled cousin I covered a few issues back. Same idea, different clock. /loop for while you’re here, Routines for while you’re not.
What Goals and Loops look like in practice
Four goals worth trying this week.
1. The campaign consistency check
/goal Every deliverable in this brief is drafted and cross-checked against the others: same offer, same price, same start and end dates, same CTA URL, same product name. Before finishing, show me a table with one row per asset and a column for each of those five, so I can see for myself that they match. Flag anything you changed. If something can’t be resolved without a decision from me, stop and ask rather than guessing. Stop after 15 turns either way.
This is the highest-value use of the feature, because cross-deliverable consistency is the one thing no single writer can check.
Each person makes their piece correctly. The mismatch is a property of the whole set, and it only surfaces if someone reads all six things side by side at the end, which nobody ever does. Run this and you’ll usually get back two or three genuine catches. Rarely the price.
Usually the archived link, the product name that changed mid-campaign, and the date that says Friday in one place and the 14th in another when the 14th is a Thursday.
2. The content batch with actual variety
/goal Three LinkedIn posts are drafted for Monday, Wednesday and Friday. Each uses a different hook type, no two open with the same sentence structure, and none reuses a story or statistic from my last month of posts. Before finishing, list the three hook types side by side and the opening line of each so I can see they’re genuinely different. Stop after 15 turns.
Batching content is efficient and it quietly kills variety.
Write three posts in one sitting and they sound like the same post three times, because you’re in one mood, drawing on one recent set of thoughts, stuck in one sentence rhythm. The variety clause is the whole point.
Without it you get three good posts your audience experiences as one repeated post, which is worse than three mediocre posts that at least feel different.
3. The pre-send email QA
/goal Every link in this email resolves, every UTM parameter follows our naming convention, the preview text is under 90 characters and doesn’t repeat the subject line, and every merge field has a fallback value. Print each link with its status, and each merge field with its fallback. If a link can’t be checked, say so explicitly rather than treating it as fine. Stop after 15 turns.
Email is the channel with no undo.
Every marketer has sent a broadcast with a broken link, and it happens because link-checking is boring, mechanical work done at the exact moment you’re most eager to hit send.
The merge-field one is the quiet killer. “Hi {{first_name}},” renders as “Hi ,” for every subscriber who came in through the form where you never collected a first name, which is usually the form that brought your best segment.
4. The research that doesn’t give up at six
/goal I have ten real competitor onboarding email subject lines, each listed with the company, the exact subject line, and a one-line note on the angle it uses. Ten, not eight. If you genuinely cannot find ten, list where you looked and what you found instead, rather than inventing any to make up the number. Stop after 15 turns either way.
Research is where AI stops early most often, because six good examples genuinely look like a complete answer.
You asked for examples, you got examples, the response reads as finished. The “ten, not eight” is deliberately blunt and it works. The final clause matters just as much, because it gives Claude an honest exit that isn’t quietly padding the list with things it made up to hit the number.
Then, once one of these earns its place, wrap it in a loop.
A weekly /loop that re-runs your competitor subject-line pull keeps your swipe file current without you remembering to do it.
A /loop over your published posts that re-checks internal links catches decay as it happens rather than at the next audit.
The goal makes the check trustworthy. The loop makes it continuous.
And this isn’t theory.
One marketer I know ran a goal across thirty blog posts, requiring every one to carry at least two internal links, with the count documented in a file as proof. It finished in about four minutes, unattended, and the checking model cost roughly two cents. A boring, important, easily-skipped job, done completely, for the price of not thinking about it.
Keep the finish line at “ready,” never “sent”
One rule I’d apply to every goal and every loop you write.
Drive work to ready. Not to sent.
It’s tempting to write “the campaign is published.” Don’t.
The moment a condition can only be satisfied by an irreversible action, you’ve handed away the part of the process where your judgement does the most work.
Keep the finish line at drafted, cross-checked, staged and waiting for you. Publishing, sending and scheduling stay manual, deliverable by deliverable.
This is the 10/80/10 principle I keep coming back to.
You do the first 10%, writing the goal and defining what done means. AI does the middle 80%, the production and the checking. You do the last 10%, reading it and deciding what ships.
Goals and loops don’t change that split.
They make the middle 80% far more reliable, and they stop it handing you 90%-complete work dressed as finished.
4 things worth knowing about Goals and Loops
1/ A goal does not change permissions, and this catches almost everyone.
Setting a goal removes the need to prompt Claude each turn. It does not remove the approval prompts on individual actions. Set a goal, wander off for a coffee, and you may come back to find it waiting on you to approve something on turn two. To genuinely leave it running, pair the goal with auto mode. Walking away is two settings, not one.
2/ Turns cost money.
The checking model is cheap to the point of irrelevance. The turns it triggers are not. A goal that runs fifteen times has done fifteen turns of real work, and a condition that can never quite be satisfied announces itself through your bill rather than through an error message. That’s the whole reason for the “stop after N turns” clause, and the same caution applies doubly to loops, which by design keep going.
3/ It’s the wrong tool for subjective work.
“This essay is compelling” has no finish line, and a second model is no better placed to judge that than the first one was. Creative judgement is precisely the part you shouldn’t hand over. Goals are at their best on the mechanical, checkable layer underneath the creative work, which is a bigger share of marketing than most of us like to admit.
4/ The checker only sees the conversation.
Worth repeating, because it’s the mistake that costs most. A confident line saying “all links checked and working” reads exactly like a real check to a model that can’t open a browser. Ask for the itemised proof, and spot-check it yourself the first few times until you trust the pattern.
The bigger picture
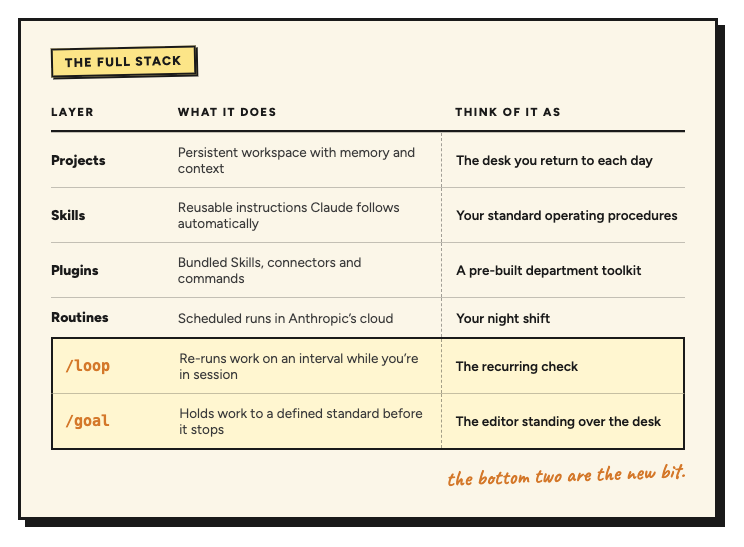
Every other layer in that table makes Claude capable of more, or gets it moving faster.
/goal is the only one that makes it stop being satisfied too easily, and /loop is the one that keeps it coming back.
Together they’re the closest thing marketing has to a self-correcting production line: get it right, then keep it right.
That’s the more interesting angle for me, because capability stopped being the constraint on AI marketing a while ago. The models can write the email, build the page, run the audit and pull the research. What they’ve been poor at is knowing when the work is genuinely finished, and when to come back and check it hasn’t drifted. Those two commands are the answer to both.
And once you’ve written a goal or a loop that earns its keep, it’s worth saving.
Drop it into a Skill, or a shared repository your whole team pulls from, and the check you wrote once becomes a check everyone runs. I made the case for that shared home in the guide to GitHub for marketers, and this is exactly the kind of asset it was built to hold.
The marketers getting the most from AI right now aren’t writing the cleverest prompts.
They’ve got specific about what finished means, written it down, and stopped accepting work that merely looks like it.
That’s a briefing skill, not a technical one.
It’s the same skill that separates a good creative director from a bad one, and it always has been.
This week’s challenge: take the next campaign or content batch on your list and write the goal before you write anything else. One condition, specific enough that a stranger could check it, with a “stop after 15 turns” on the end. Run it, and see what comes back on the list of things it found and fixed. Then, if it earns it, wrap it in a weekly loop. Reply and tell me what it caught. I’m genuinely curious whether it’s the price mismatch or the dead link.
Thanks for reading Marketing with AI. If you found this useful, sharing it with one other marketer is the best compliment I could receive.
Need 1:1 Help to Embed Claude into Your Marketing?
I work with organisations to automate tasks, streamline workflows, and get more done with AI - building the skills, systems and workflows that turn Claude into their marketing operating system. Consulting, coaching and training, in person or on demand.
From 0.5 days overviews to 2-day workshops, I can help you automate more marketing work and streamline your workflows to get mroe done with AI. I offer both in-person and online sessions to suit your needs.