
Every Wednesday, one essay on what's actually working in Marketing with AI - tools, workflows, and mindset shifts you can apply immediately.
NB: This article contains 3 short videos showing you how to browse the Apify store to find relevant scrapers, connect Apify to Claude, and then run your first search.
Let me guess your reaction to the words “web scraping.”
It will likely be one of the following:
1/ It sounds very technical. Something involving Python scripts, proxies, and a developer you’d need to hire.
2/ It sounds vaguely illegal. Scraping data off websites feels like it shouldn’t be allowed.
Both reactions are fair, and I would have thought it was a bit ‘dodgy’ several years ago to. But both mindsets for me are now outdated.
Because here’s what’s changed: Claude can now scrape data from thousands of websites using plain English prompts.
You don’t need to code. You don’t need complicated APIs. And you certainly don’t need a developer.
You just need to open a new Claude Cowork session and describe what you want. Claude then goes and gets it.
“Find me 20 digital marketing agencies in Manchester with fewer than 50 employees.”
The tool making this possible is called Apify.
You’ve might not have heard of it, and that’s fine.
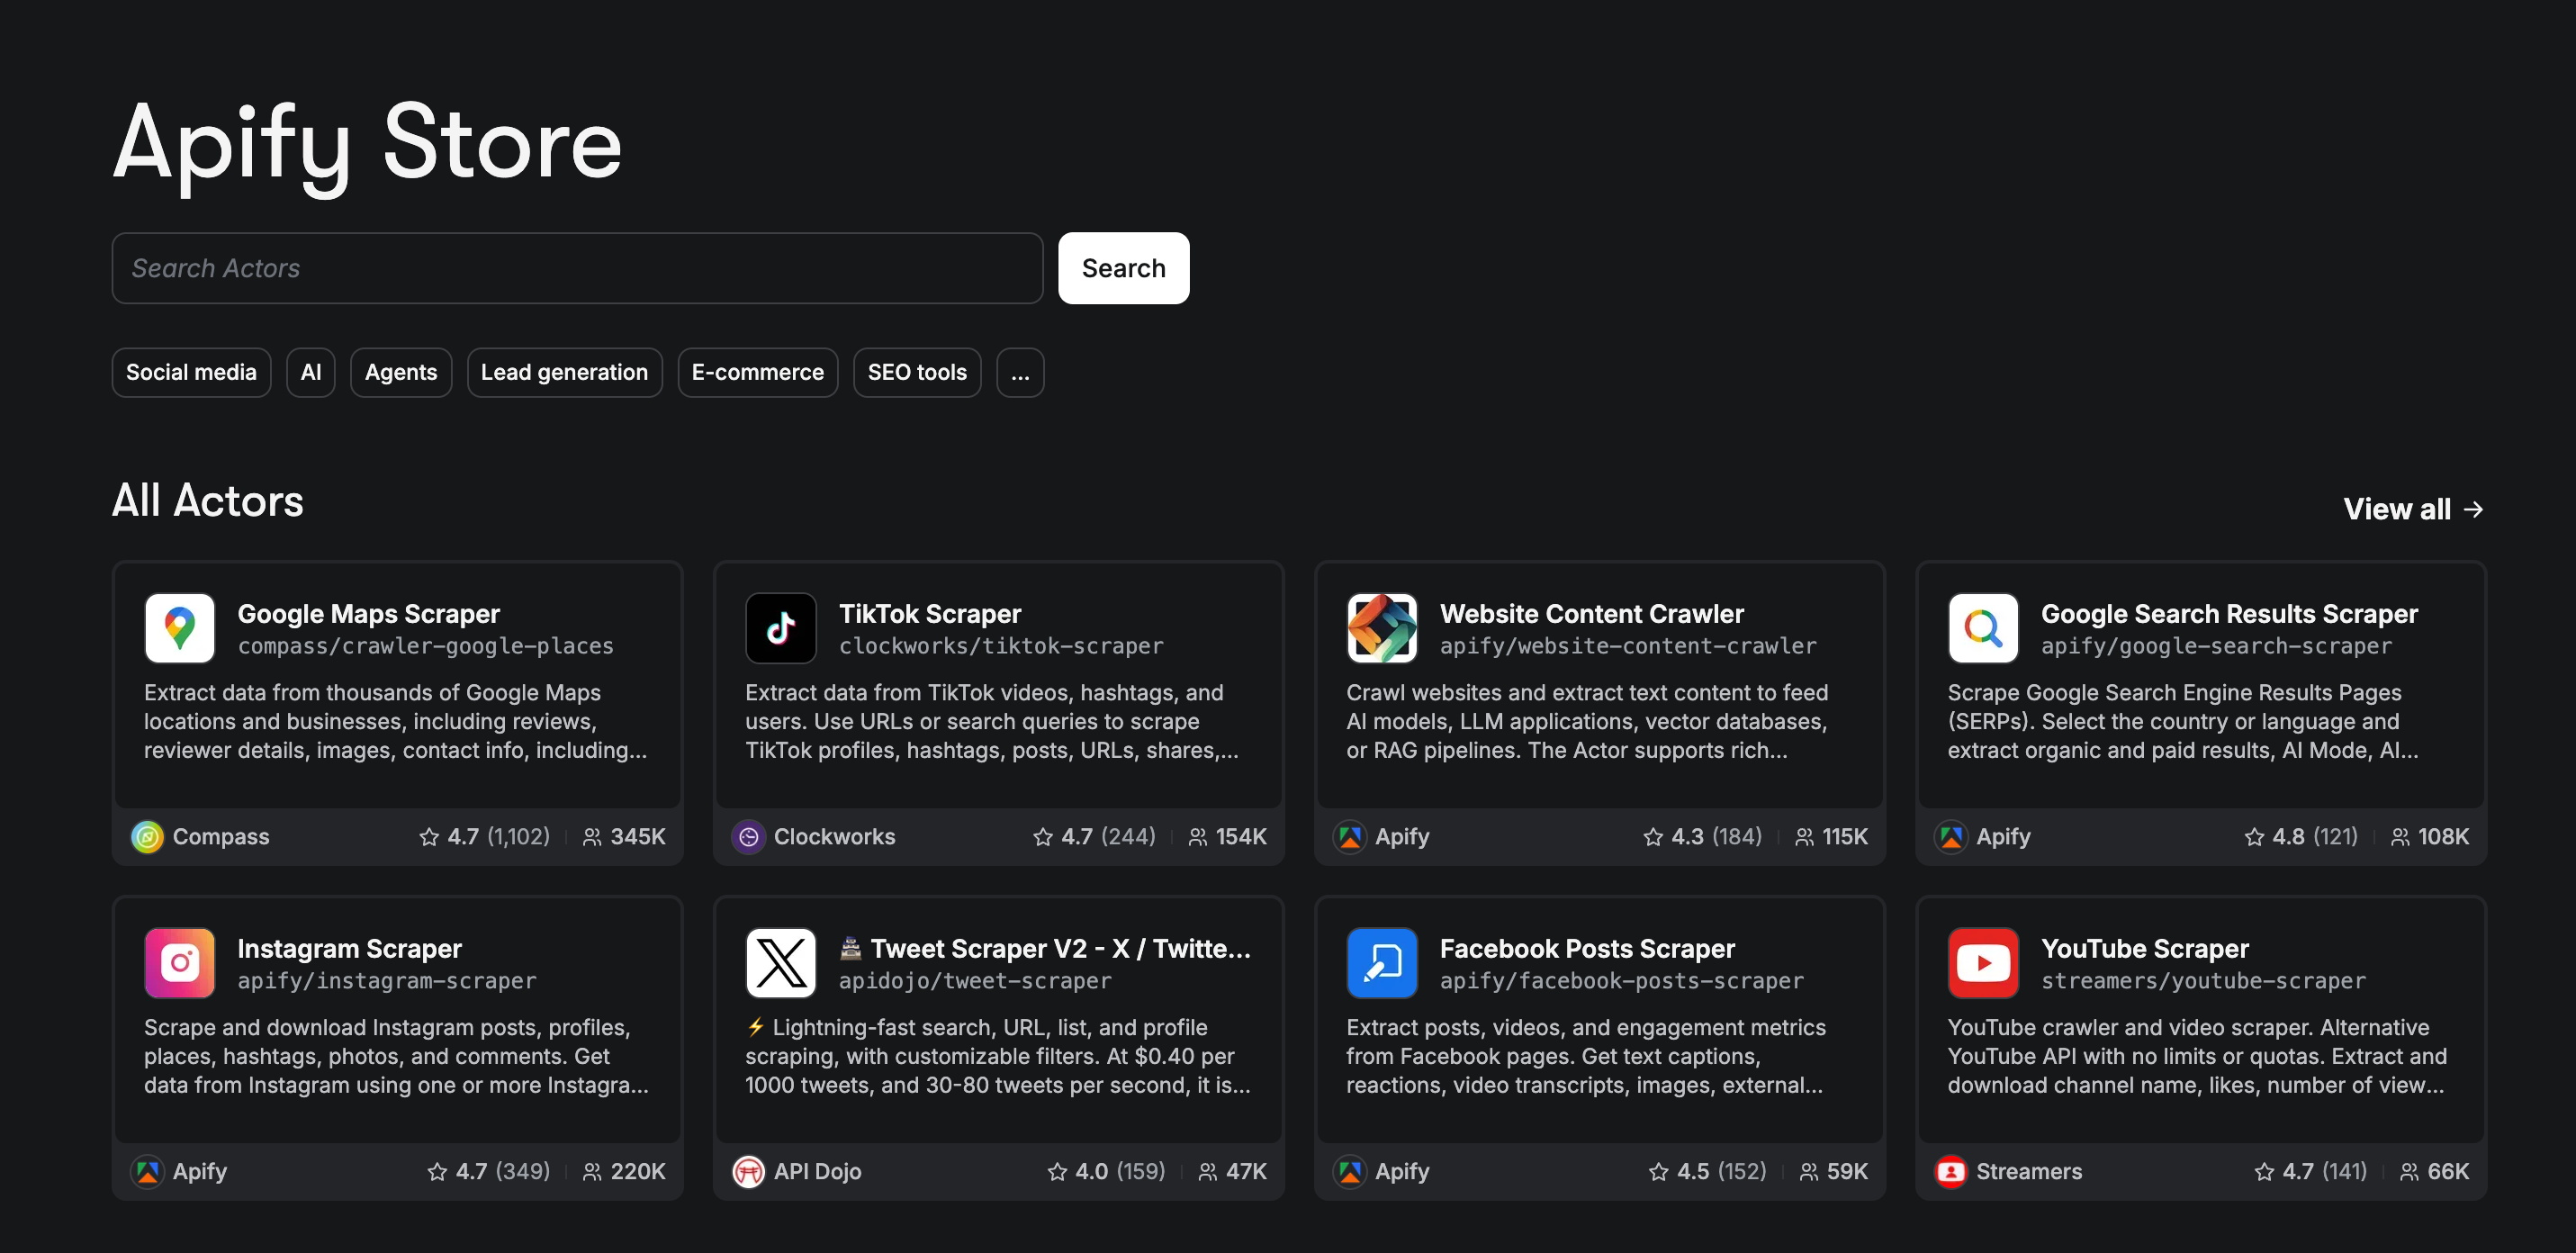
Think of it as an app store for data collection, with over 15,000 pre-built scripts (they call them “actors”) that can extract structured data from Google Maps, LinkedIn, Reddit, TripAdvisor, Instagram, TikTok, Facebook Ads, Amazon, and practically every other platform you can think of.
And as of early 2026, Apify plugs directly into Claude. One connector. Two minutes to set up. Then you just ask for what you need.
Apify gives Claude access to the outside world, so it can go and find things for you, not just work with what you already have.
What Is Apify (And Why Should You Care)?
Apify is a platform with over 15,000 pre-built data extraction tools. Each tool (called an “actor”) is designed to collect specific data from a specific platform.
1/ Want business listings from Google Maps? There's an actor for that (201,000+ users of that actor as of typing).
2/ Need engagement data from TikTok? There's one for that.
3/ LinkedIn profiles, Instagram posts, competitor pricing pages, Amazon product listings? All covered.
📹 Here’s a quick overview of the Apify Store
If a platform exists, there's probably an Apify actor that can pull data from it.
The clever bit is how this connects to Claude.
Through something called MCP (Model Context Protocol), Claude can discover, select, and run the right actor automatically.
The beaty of it is, you don’t need to know which actor to use and you don’t need to understand the MCP. Just describe the data you want, and Claude figures out which actor to use and runs it for you.
Here’s what happens when you make a request:
1. You describe what data you want in plain English
2. Claude searches Apify’s marketplace and picks the right actor
3. Claude configures and runs it with appropriate limits
4. The results come back into your conversation
5. Claude formats, analyses, or exports the data however you need
No switching between tools. No configuring API endpoints. One conversation from request to results.
Think of it like this: Apify is a massive library of data collection tools. Claude is the assistant who knows which tool to grab and how to use it. You just tell it what you need.
I read the other week a piece from Hiba Fathima, SEO lead at Firecrawl, who replaced multiple SaaS subscriptions with tools she built herself using Claude and web scraping with Apify.
Why This Changes Things for Marketers
Here’s the reality most marketers live with:
The data you need to do your job well is scattered across dozens of platforms, and collecting it manually is slow, boring, and expensive.
You want to know what your competitors are spending on Facebook Ads? That’s a manual check. You want a list of potential clients in your area? That’s an afternoon on Google Maps with a spreadsheet. You want to understand what questions your audience is asking on Reddit? That’s hours of scrolling.
All of that is now a single prompt.
What used to take hours takes minutes. What used to require a developer requires a sentence.
And we haven’t even touched on the cost which for me is almost absurdly low. A typical data collection task costs around $0.01–$0.05.
I recently scraped multiple LinkedIn content posts to analyse messaging of a competitor. Scraping around 150 of their last posts cost me around $1.
I know a marketing peer who is pulling competitor Facebook ads for $0.02.
And believe it or not, Apify’s free tier gives you $5/month in credit, enough to run dozens of small tasks before you have to spend a penny.
Compare that to the alternatives: hiring a virtual assistant ($500–1,000/month), subscribing to a lead gen platform ($100–300/month), or paying an agency ($2,000+/month) for the same data.
But speed and cost aren’t the real shift. The real shift is what becomes possible when data collection is easy.
When scraping Google Maps takes 30 seconds instead of 3 hours, you stop doing it quarterly and start doing it weekly. When monitoring competitor ads costs $0.02 instead of a SaaS subscription, you stop checking monthly and start checking daily. When pulling Reddit insights takes one prompt instead of an afternoon, you stop guessing what your audience cares about and start knowing.
Easy data collection doesn’t just save time. It changes your mindset and the questions you’re willing to ask.
Setting Up Your First Apify Connection
This takes about two minutes. Genuinely.
Step 1: Create an Apify Account
Head to apify.com and sign up. The free tier gives you $5/month in credit every month, more than enough to test everything in this article.
Step 2: Get Your API Token
In Apify, go to Settings → API & Integrations. Copy your API token. You’ll need it in a moment.
Step 3: Connect Apify to Claude
Open Claude Desktop and switch to Cowork mode. Click Customise → Connectors → Click the + icon →Browse Connectors. Search for “Apify.” Click Install. Paste your API token. Save.
That’s it. Claude now has access to 15,000+ data collection tools.
Step 4: Test It
Ask Claude something simple to verify the connection works:
“Find 5 coffee shops in central London on Google Maps. Return the name, rating, phone number, and website for each.”
If you get a clean table back, you’re ready.
📹 Here’s how to connect Apify to Claude
One important note: Always set limits in your prompts. “Find 5 coffee shops” is good. “Find all coffee shops in London” will burn through credits fast and potentially time out. Start small, verify the results, then scale up.
Six Marketing Workflows You Can Run This Week with Apify
1. Local Business Lead Generation
This is the most popular use case for a reason. It works immediately and the value is obvious.
Ask Claude: “Find 20 digital marketing agencies in Birmingham on Google Maps. Return business name, phone number, email, website, Google rating, and review count. Filter for businesses with ratings above 4.0. Export to a spreadsheet.”
Claude selects the right Apify actor (Google Maps Scraper or alternative), runs the search, and returns structured data ready for outreach.
Taking it further: Ask Claude to visit each website and check whether they have a blog, an active social media presence, or any obvious gaps in their digital marketing. Now you’re not just collecting leads, you’re qualifying them and building a personalised pitch in the same conversation.
One creator I researched for this article, documented finding businesses without websites via Google Maps, then building simple sites for them and charging £100–120/month. The entire prospecting pipeline (find, qualify, outreach) runs from a single Claude session.
2. LinkedIn Prospecting with Personalised Outreach
This is the one most B2B marketers will reach for first. I certainly did.
Finding prospects who match your ideal customer profile is straightforward enough. Finding them and having something genuinely personalised to say? That’s the part that usually takes hours.
Ask Claude: “Find 20 heads of marketing at B2B SaaS companies in London using LinkedIn. Extract their name, company, role, and their 3 most recent LinkedIn posts. For each person, draft a personalised connection request that references something specific from their recent content.”
Claude uses an Apify LinkedIn actor (one popular option has a 99.8% success rate), pulls the profile and post data, then writes outreach messages that sound like you actually read their feed - because Claude actually did. And it can add all of this to a nice spreadsheet if you want it to.
The difference this makes: Generic connection requests get ignored. A message that opens with “I saw your post about [specific topic] and...” gets read. This workflow automates the research that makes personalisation possible at scale, without sacrificing the quality that makes it work. You can also stack data sources - use Apify for LinkedIn profiles and a separate enrichment connector for verified email addresses, all within the same conversation.
3. Competitor Ad Monitoring
Every marketer wants to know what their competitors are running on Facebook and Google. Most check manually every few weeks. With Claude and Apify, you can automate this daily.
Ask Claude: “Check the Facebook Ad Library for [competitor name]. Find any ads that have been running for more than 7 days. For each ad, extract the headline, primary text, call to action, and landing page URL. Summarise the messaging themes and note anything that’s changed since last week.”
The real power here is scheduling. Use /schedule inside Claude Cowork to run this every Monday morning. Claude checks your competitors’ ads, summarises what’s new, flags changes in messaging, and delivers a report. All before you’ve finished your first coffee.
Over time, you build an intelligence layer that most marketing teams simply don’t have. You stop reacting to competitor moves and start anticipating them.
4. Reddit and Social Listening for Content Ideas
This one is underrated.
Reddit is the largest focus group on the internet, and most marketers never touch it because trawling through subreddits is time-consuming.
Ask Claude: “Search the r/marketing and r/digital_marketing subreddits. Find the top 20 posts from the last 30 days ranked by engagement. For each post, extract the title, the top 3 comments, and the core question or frustration being expressed. Then generate 5 content ideas based on the most common themes.”
In five minutes, you’ve got a content calendar built on what your audience is actually talking about, not what you think they’re talking about.
The scheduling angle again: Set this to run weekly. Every Monday, Claude delivers a “what your audience is asking about” briefing pulled from live conversations. One creator I researched turned this into a $500/month service, selling automated Reddit intelligence reports to clients.
5. Competitor Content and Pricing Intelligence
Most marketers keep a vague eye on what their competitors are doing.
Few have a systematic process for tracking it. This workflow changes that.
Ask Claude: “Crawl [competitor website URL]. Extract all blog post titles published in the last 60 days with their URLs and estimated word counts. Then visit their pricing page and extract all plan names, prices, and listed features. Compare their pricing to ours: [your pricing]. Summarise key differences and any content topics they’re covering that we’re not.”
You get a competitive content gap analysis and a pricing comparison in one conversation.
Monthly scheduling makes this compound. Run it on the first of every month and you build a historical view of how competitors are shifting their messaging, pricing, and content strategy. After three months, you’re spotting patterns that would take a dedicated analyst to track manually.
6. Turning Scraped Data Into Original Content
This is the angle most people miss and I love this one.
Everyone talks about using scraped data for leads. Almost nobody talks about using it to create content.
Ask Claude: “Scrape 200 job listings for ‘marketing manager’ roles in the UK from LinkedIn. Analyse the listings and tell me: what percentage mention AI skills? What are the top 10 most-requested skills? What’s the average salary range? What are the most common seniority levels? Then write a short data-driven article titled ‘What UK Marketing Employers Are Really Looking For in 2026’ based on the findings.”
One creator I researched did exactly this and I’ve done something similar myself. He scraped 50 job listings, found that just 2% explicitly required AI skills, and turned it into a PR-ready report. That’s the kind of original data journalism that earns backlinks, social shares, and media coverage.
Other content angles you can build from scraped data:
1/ “The State of Pricing in [Your Industry]” from monthly competitor pricing scrapes.
2/ “What [Your Audience] Is Actually Complaining About” from G2 and TrustPilot review analysis.
3/ “This Week in [Your Niche]” from weekly Reddit and Twitter monitoring.
Data collection isn’t just a sales tool. It’s a content engine.
📹 Here’s how to run an Apify search inside Claude
What Scraping Data Actually Costs
Most content on this topic glosses over the numbers. Here’s the full picture.
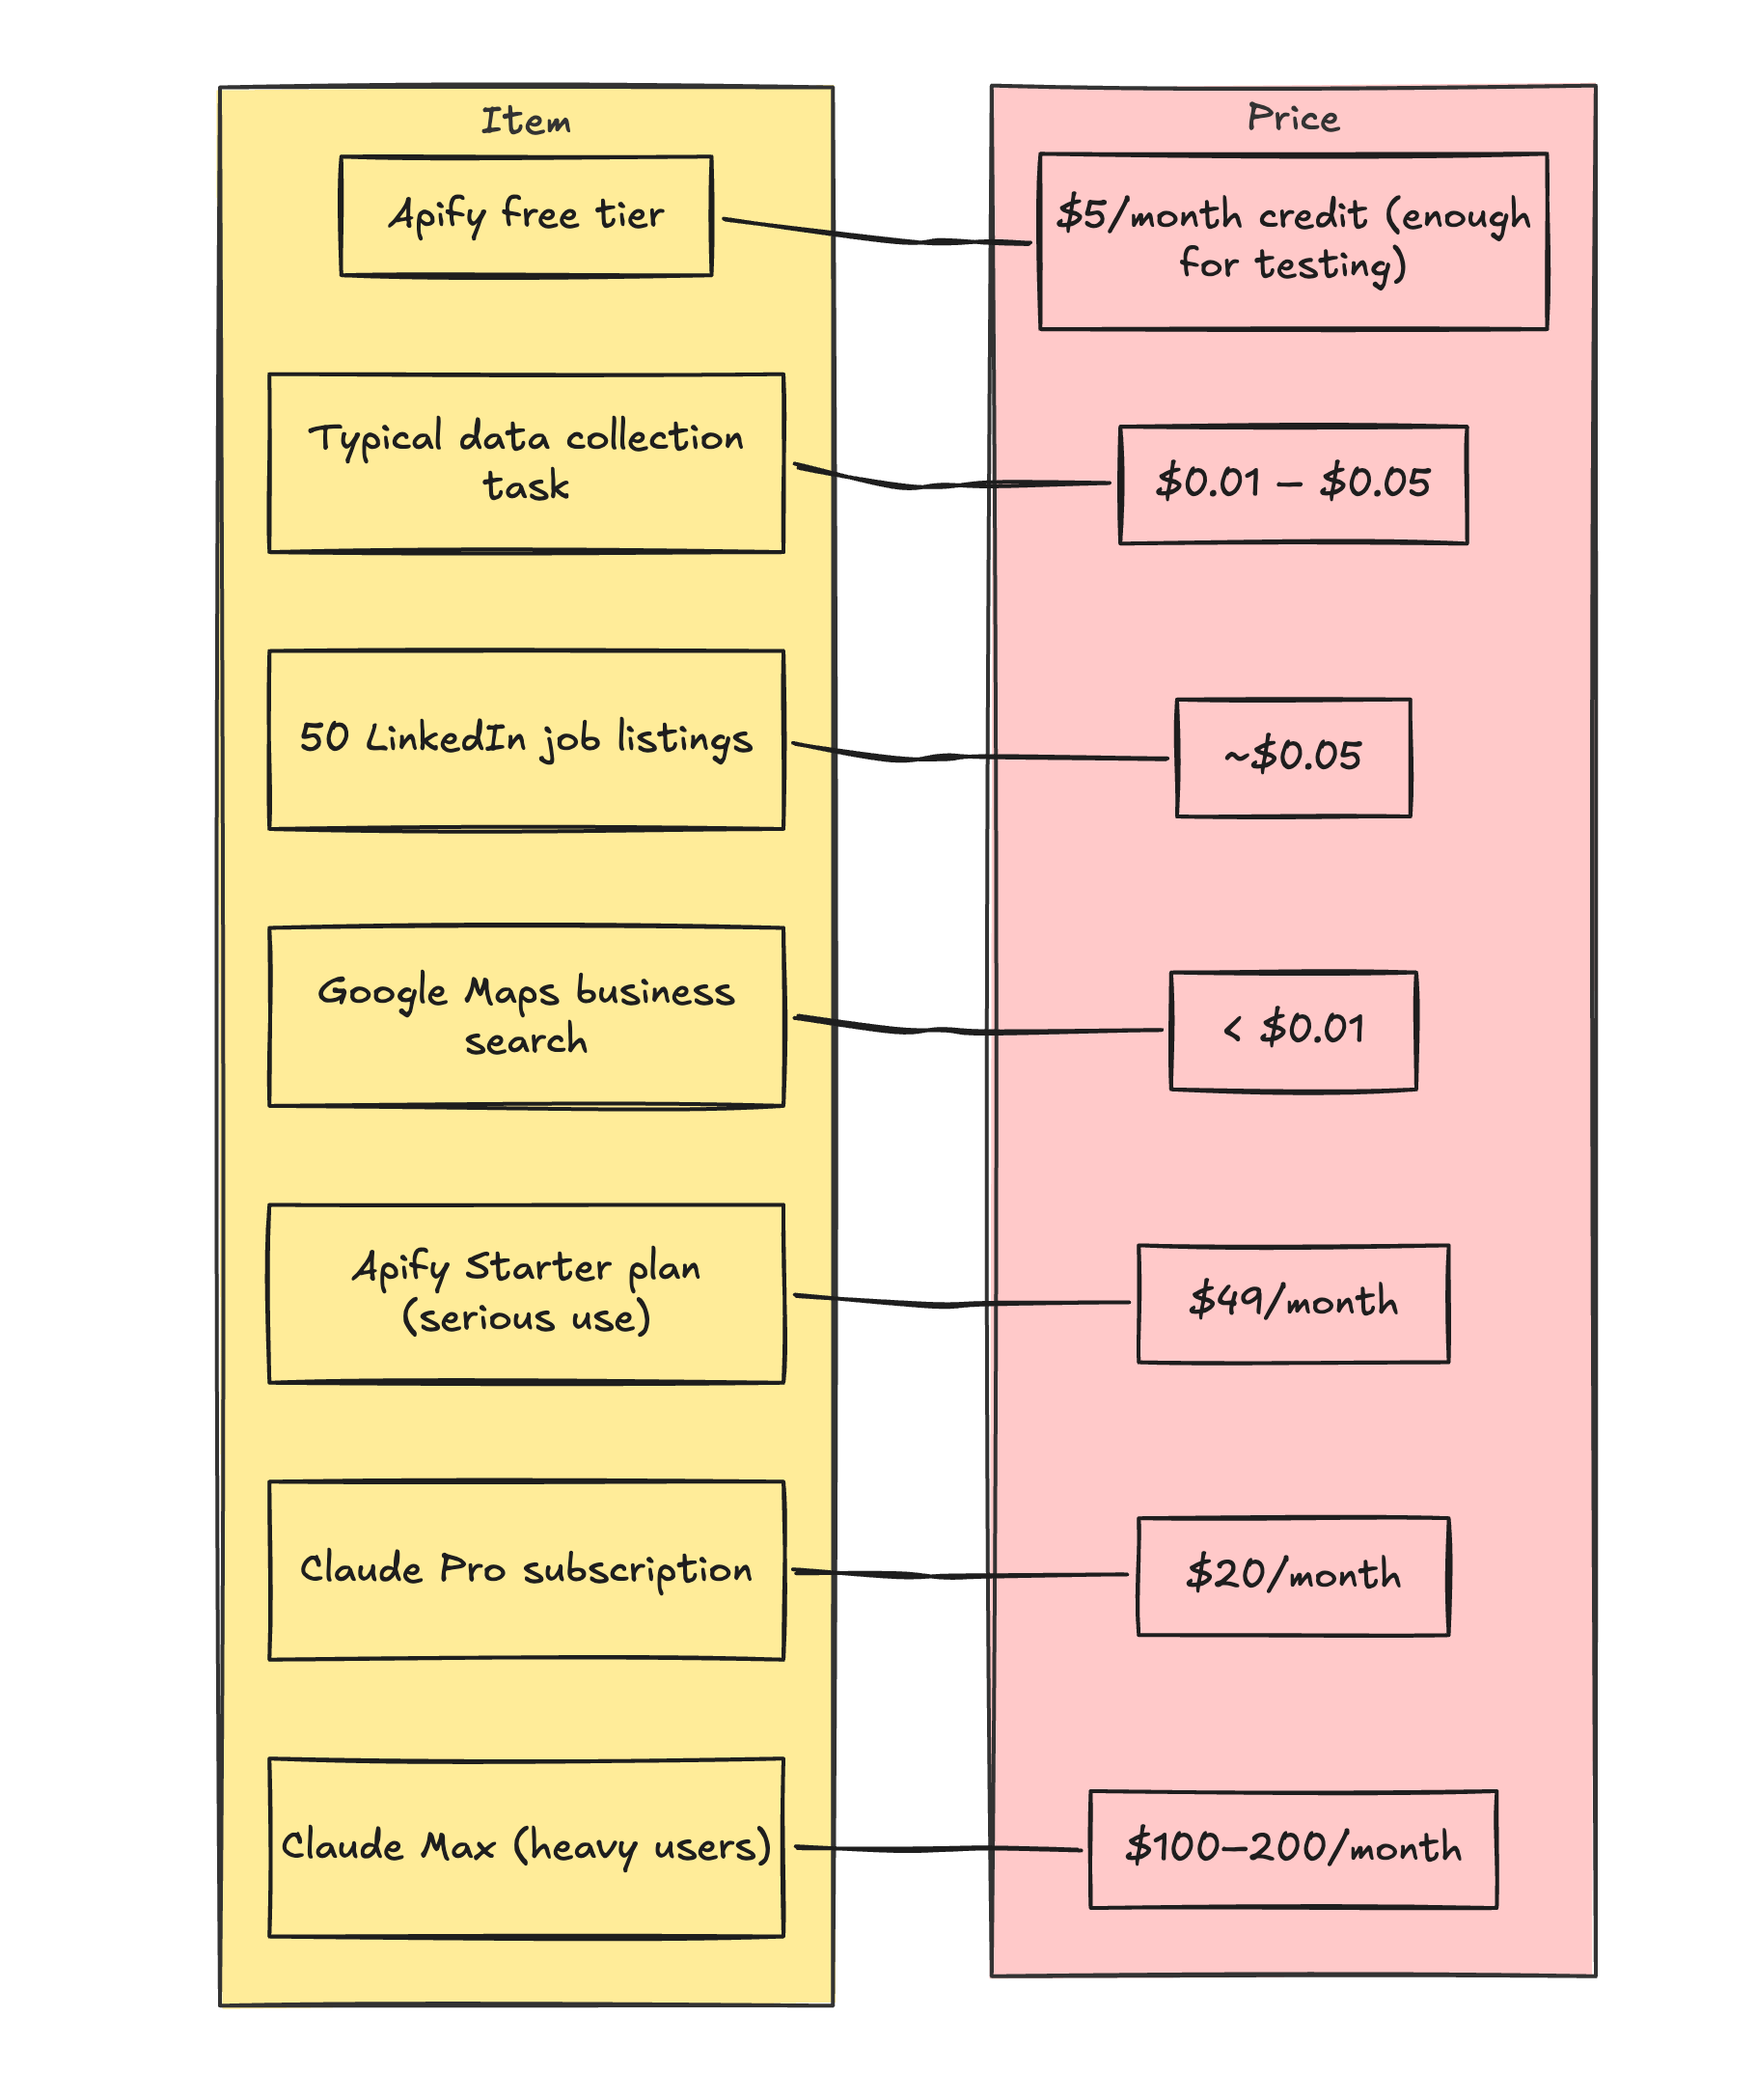
Realistic monthly budget: Claude Pro + Apify Starter = $69/month for a solid marketing data pipeline. Compare that to a virtual assistant ($500–1,000/month) or an agency ($2,000+/month) for the same research work.
For most readers, the free Apify tier is enough to test every workflow in this article. You only need Starter if you’re running daily automations or large-scale scrapes.
The Responsible Marketer’s Checklist
I always include caveats because they matter. And with data collection, the legal and ethical side matters more than usual.
Web scraping is not illegal. But it’s not a free-for-all either. Here’s what to keep in mind:
• Business data vs. personal data: Scraping business names, addresses, phone numbers, and websites from Google Maps is generally low risk. Scraping individual names, personal email addresses, and LinkedIn profiles carries higher obligations under GDPR. Know the difference.
• “Public” doesn’t mean “free to take.” Under UK GDPR, privacy laws apply to personal data regardless of whether it’s publicly visible. Someone’s name on a LinkedIn profile doesn’t automatically mean you can collect and use it without obligations.
• Set clear limits. Only collect data you actually need for a stated purpose. Data minimisation isn’t just good practice. It’s a legal requirement under GDPR.
• Respect robots.txt and terms of service. If a website explicitly blocks scraping, respect that. Bypassing technical measures could breach the Computer Misuse Act 1990.
• If you contact someone using scraped data, be transparent. They have a right to know where you got their information and how to opt out.
• Don’t hoard data. Use it, then delete what you don’t need. Retention matters.
The short version: don’t collect data you wouldn’t want collected about yourself. If your outreach would feel invasive if you were on the receiving end, rethink the approach.
The Honest Caveats
Beyond the legal considerations, here’s what else to know:
Apify’s free tier has limits. $5/month in credits goes quickly if you’re running large scrapes or daily automations. See the cost breakdown above for what to expect at scale.
Results need human review. Email addresses aren’t always accurate. Business listings can be outdated. Some actors return cleaner data than others. Always verify before using data for outreach. Bad data means bad reputation.
Claude Desktop must stay open. Scheduled tasks only run while your computer is awake and Claude Desktop is open. Close the lid and tasks get skipped. There’s no cloud sync yet.
Token consumption is real. A complex multi-step workflow (find leads, visit their websites, enrich with contact details, write personalised emails) can consume the equivalent of 20+ regular chats. Heavy users should consider the Max plan ($100–200/month).
Actors can change. Apify’s scrapers are maintained by their creators. Occasionally one goes down, changes pricing, or needs updating. The good news is Claude usually auto-detects this and switches to an alternative actor. But it’s worth knowing the infrastructure isn’t static.
Start small. Your first instinct will be to scrape 500 leads at once. Don’t. Start with 10–20 results. Verify the quality. Refine your prompt. Then scale up. The prompting tip that matters most: always specify explicit limits so a task doesn’t spiral.
The Big Picture Claude Ecosystem
Here’s what I want you to see.
Data collection isn’t a standalone trick. It’s the starting point for everything else Claude can do.
Think about it. You run a weekly competitor ad monitoring scrape. Claude collects the ads, analyses the messaging themes, and compares them to last week’s data. It then builds a competitive intelligence spreadsheet with trend charts, exports a summary into a strategy deck for your Monday morning meeting, and saves the whole thing into your Project so next week’s report builds on this one.
One conversation. Data collection, analysis, spreadsheet, presentation, and outreach copy. No switching tools. No re-explaining context.
That’s what happens when you connect data collection to the ecosystem you’ve already built. Your Skills keep the outputs on-brand. Your Project remembers what worked last time. Your Plugins give Claude specialist knowledge. And your Connectors pull in data from Slack, Gmail, your CRM, whatever else you’ve wired up.
Scraping is the input. The rest of the ecosystem is what turns that input into actual marketing output.
The marketers who will get the most from this won’t be the ones running the biggest scrapes. They’ll be the ones who connect scraping to the workflows they’ve already built, and let the whole system compound.
Want hands-on help with Claude?
I work with marketers 1:1 in Claude Marketing Power Hours and help teams embed Claude into their workflows from first steps to full-scale systems. Book a call using the link below.
Thanks for reading Marketing with AI! If you enjoyed this read, the best compliment I could receive would be if you shared it